The Full Transformer — Encoder + Decoder
Attention does the work. Residuals, normalization, the feed-forward layer, and cross-attention are the scaffolding that lets you stack it deep.
Learning Objectives
- Name the six pieces of a transformer block and say what each one does.
- Wire a pre-norm encoder block and a decoder block (masked self-attention, cross-attention, FFN), and explain where encoder information enters the decoder.
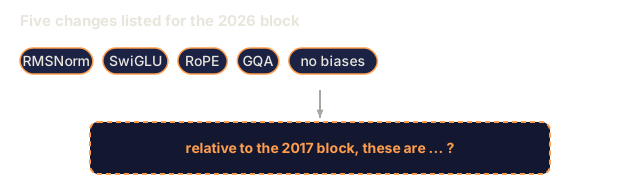
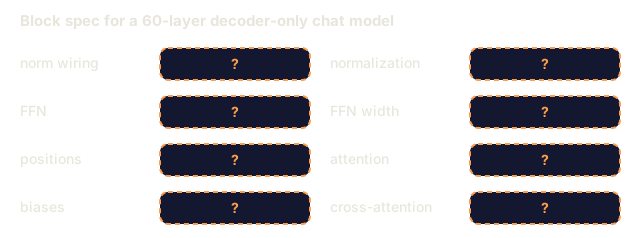
- Describe the 2026 block (RMSNorm, SwiGLU, RoPE, GQA, no biases) as substitutions into the same 2017 skeleton.
- Estimate parameters per block and per stack from d_model and the FFN expansion ratio.
The Problem
A single attention layer is a feature extractor, not a model. One matmul per layer doesn't give you enough capacity for language, so you need depth, and depth breaks without the right plumbing.
The 2017 Vaswani paper packaged six design decisions that turned one attention layer into a stackable block. Encoder-only (BERT), decoder-only (GPT), and encoder-decoder (T5) models all inherit that skeleton. By 2026 the parts have been refined (RMSNorm, SwiGLU, pre-norm, RoPE), but the skeleton is the same.
This is the skeleton. The next lessons specialize it: 06 for encoders, 07 for decoders, 08 for encoder-decoder.
The Concept

A transformer block is an attention sublayer and a feed-forward sublayer, each wrapped in a residual connection and a normalization step. (A decoder block adds a cross-attention sublayer between the two.) A transformer is a stack of these blocks on top of an embedding and positional signal. Encoder-decoder models like T5 run two such stacks.
The six pieces
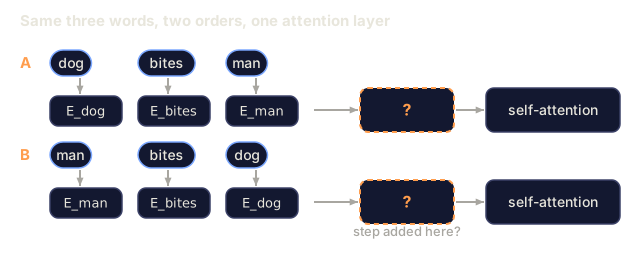
- Embedding + positional signal. Tokens become vectors. Position is injected via RoPE (modern) or sinusoidal encoding (classic).
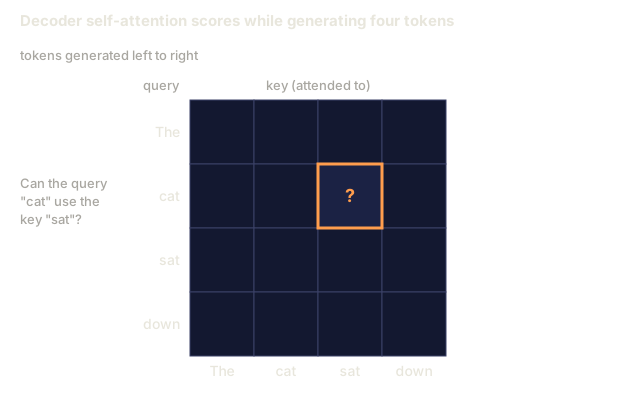
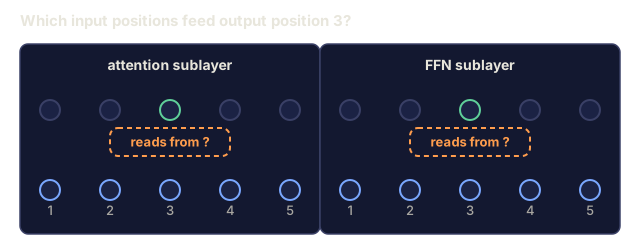
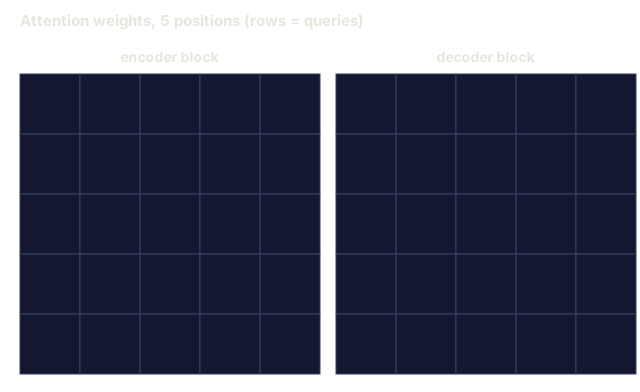
- Self-attention. Each position attends to every other position. Decoders mask it.
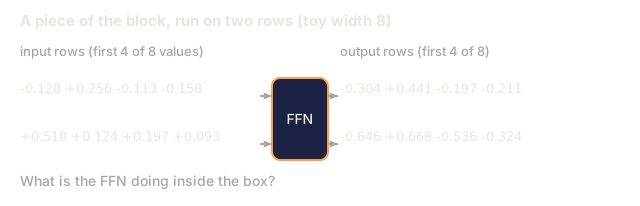
- Feed-forward network (FFN). A position-wise two-layer MLP:
W_2 · activation(W_1 · x). The expansion ratio is 4× by default. - Residual connection.
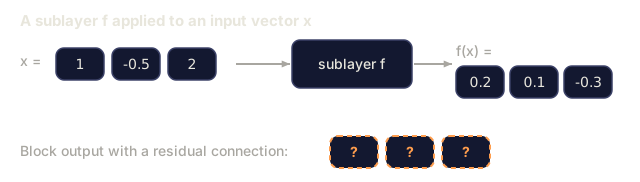
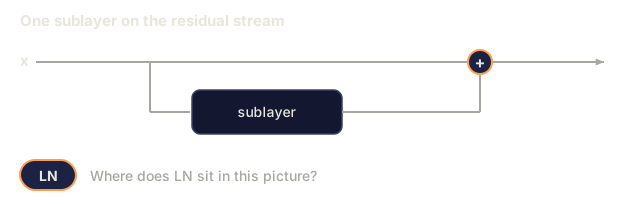
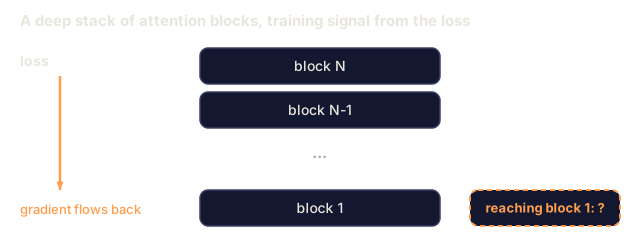
x + sublayer(x). Without it, gradients vanish past ~6 layers. - Layer normalization.
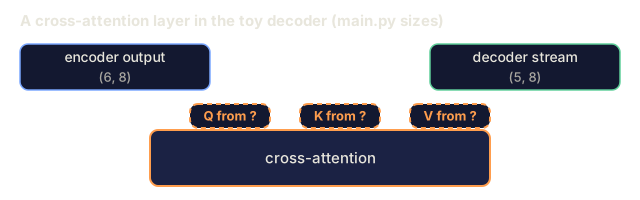
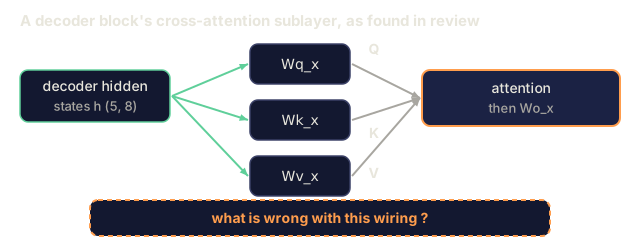
LayerNormor, in modern stacks,RMSNorm. It stabilizes the residual stream. - Cross-attention (decoder only). Queries come from the decoder, keys and values from the encoder output.
Watch a vector flow through one block: attention mixes across positions, the residual carries it forward, the FFN transforms it, and norm keeps the stream stable.
Encoder block (used by BERT, T5 encoder)
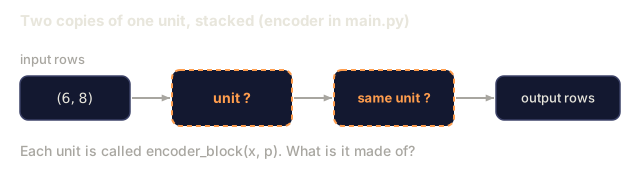
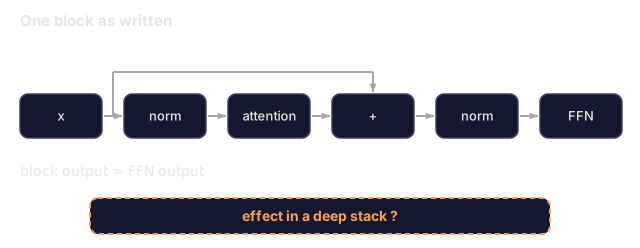
x → LN → MHA(self) → + → LN → FFN → + → out
                     ^              ^
                     |              |
                     └── residual ──┘
The encoder is bidirectional. There is no masking, so all positions see all positions.
Decoder block (used by GPT, T5 decoder)
x → LN → MHA(masked self) → + → LN → MHA(cross to encoder) → + → LN → FFN → + → out
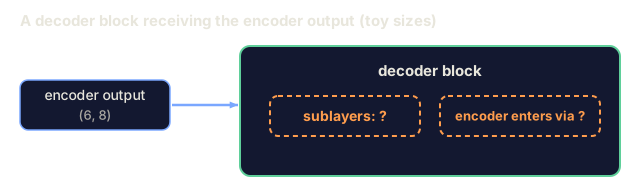
The decoder has three sublayers per block. The middle one, cross-attention, is the only place information flows from encoder to decoder. A pure decoder-only architecture (GPT) omits it, leaving masked self-attention plus the FFN.
Pre-norm vs post-norm
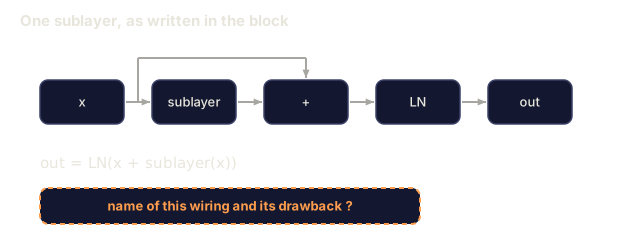
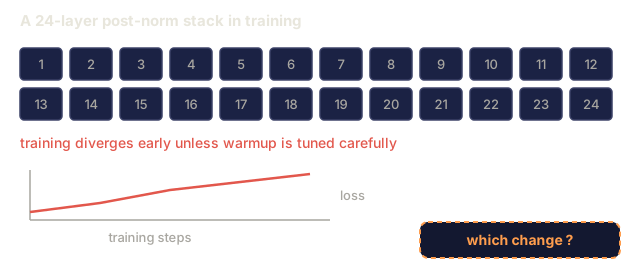
Post-norm, as in the original paper, is LN(x + sublayer(x)). Pre-norm is x + sublayer(LN(x)). Post-norm lost favor around 2019 because it is harder to train deeply without careful warmup. Pre-norm, with LN before the sublayer, is the 2026 default in Llama, Qwen, GPT-3+, and Mistral.
The 2026 modernized block
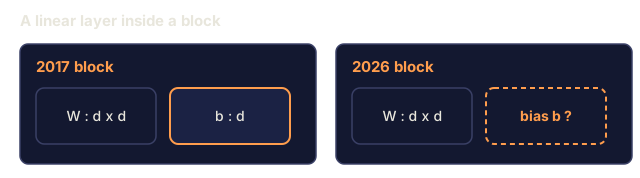
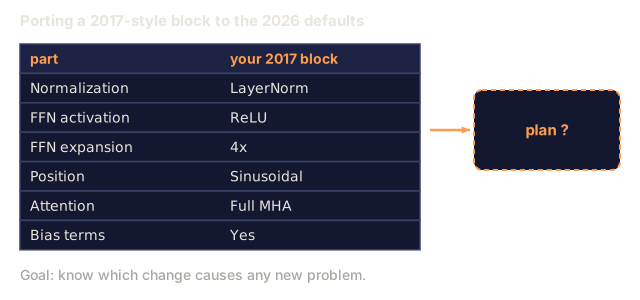
Vaswani 2017 shipped LayerNorm and ReLU. Modern stacks replaced both. Here is what production blocks look like now:
| Component | 2017 | 2026 |
|---|---|---|
| Normalization | LayerNorm | RMSNorm |
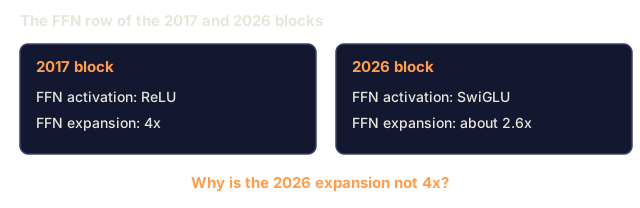
| FFN activation | ReLU | SwiGLU |
| FFN expansion | 4× | 2.6× (SwiGLU uses three matrices, total params match) |
| Position | Sinusoidal absolute | RoPE |
| Attention | Full MHA | GQA (or MLA) |
| Bias terms | Yes | No |
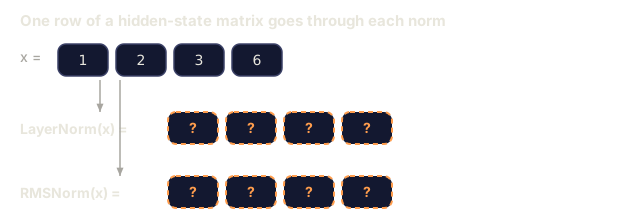
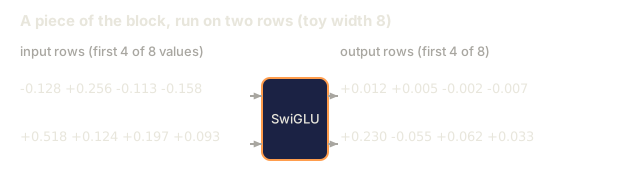
RMSNorm drops the mean-centering step of LayerNorm. That is one fewer subtraction, which saves compute, and it is empirically at least as stable. SwiGLU (Swish(W1 x) ⊙ W3 x) beats the ReLU/GELU FFN by ~0.5 point ppl in the Llama, PaLM and Qwen papers.
Parameter count
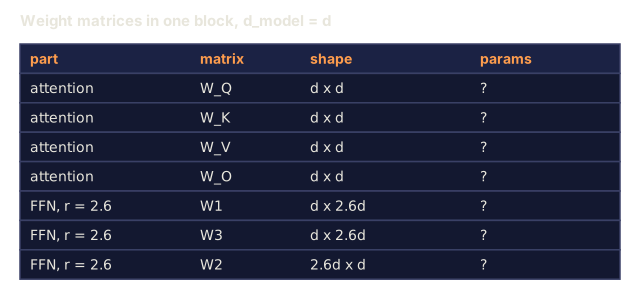
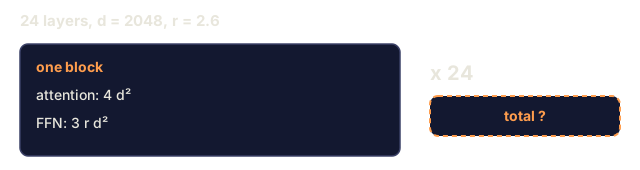
For one block with d_model = d and FFN expansion r:
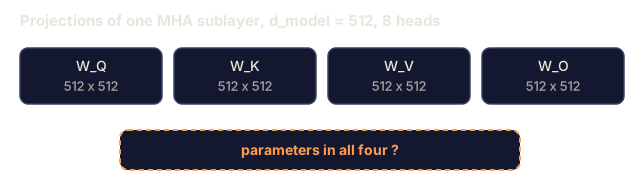
- MHA:
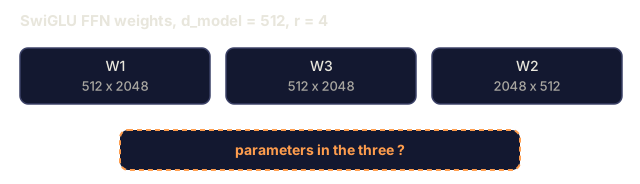
4 · d²(Q, K, V, O projections) - FFN (SwiGLU):
3 · d · (r · d)≈3rd² - Norms: negligible
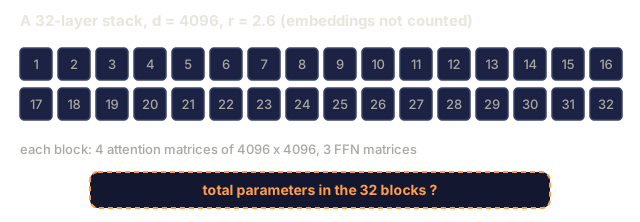
At d = 4096, r = 2.6 (roughly the shape of Llama 3 8B):
- MHA:
4 · 4096²≈ 67M - FFN (SwiGLU):
3 · 2.6 · 4096²≈ 131M - One block: ≈ 198M
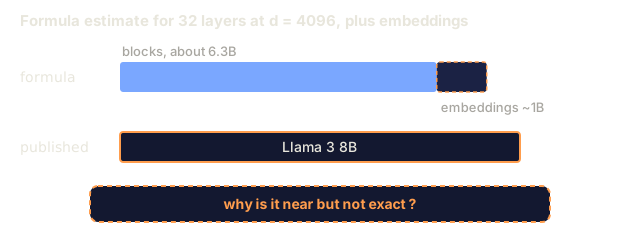
Over 32 layers that is ≈ 6.3B parameters, before embeddings and the output head, which add on the order of a billion more. That lands in the 7-8B range of the published model. The match is approximate, because Llama 3 8B uses GQA (smaller K and V projections) and a different FFN width than this formula assumes.
Build It
Step 1: the building blocks
Start with the tiny Matrix class from Lesson 03, copied into this file so it runs on its own. The pieces:
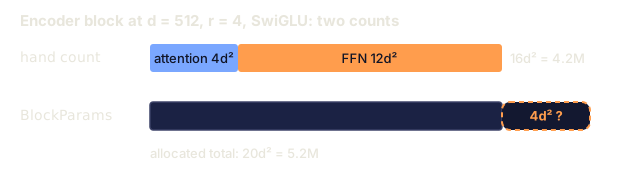
layer_norm(x, eps=1e-5): subtract the mean, divide by the std. It is defined for comparison, but the blocks never call it.rms_norm(x, eps=1e-6): divide by the RMS, with no mean subtraction. Every norm in the blocks is this one. Neither norm has a learned scale.silu(x), used insideffn_swiglu(x, W1, W2, W3):silu(x W1) ⊙ (x W3), thenW2.ffn_relu(x, W1, W2)is the classic alternative.BlockParams(d, n_heads, ffn_expansion, rng, use_swiglu=True): the weights for one block. It also allocates the cross-attention weights (Wq_xand friends) whether or not the block uses them, so an encoder block carries four unusedd × dmatrices.encoder_block(x, params)anddecoder_block(x, enc_out, params).
See code/main.py for the full wiring.
Step 2: wire a 2-layer encoder and a 2-layer decoder
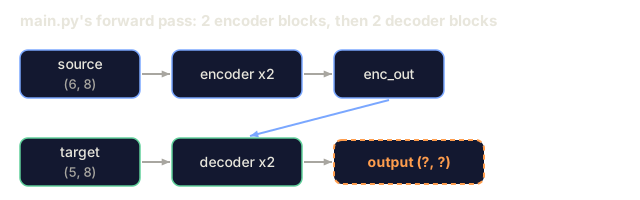
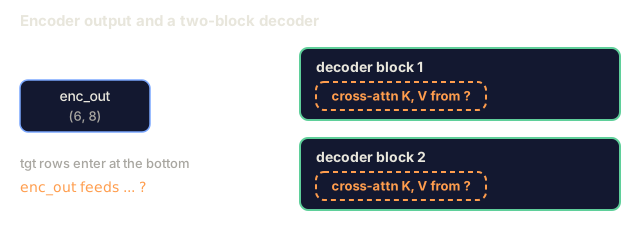
Stack the blocks, and pass the encoder output into the cross-attention of each decoder block:
enc_out = src
for p in enc_params:
    enc_out = encoder_block(enc_out, p)

dec_out = tgt
for p in dec_params:
    dec_out = decoder_block(dec_out, enc_out, p)
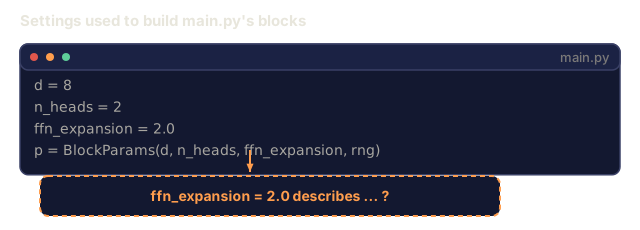
The demo runs at toy scale: d = 8, 2 heads, FFN expansion 2.0. It skips token embeddings, positional encoding, a final norm, and the output projection. main() feeds random (len, d) matrices straight into the block loops, so the architecture is the whole point.
Step 3: run forward on a toy example
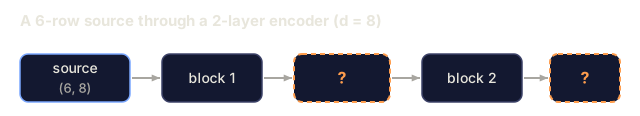
Feed a 6-row source and a 5-row target through the stack. The encoder output is (6, 8) and the decoder output is (5, 8), which is (tgt_len, d). A full model would add a final norm and a projection to (5, vocab), but this code stops before that. There's no training here. The goal is the architecture, not the loss.
Step 4: swap one component at a time
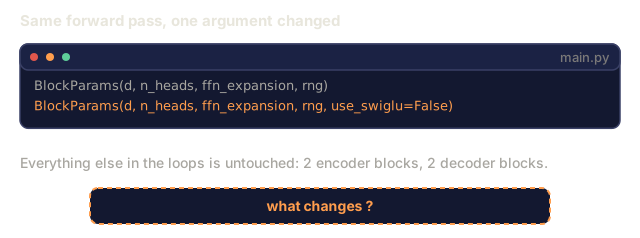
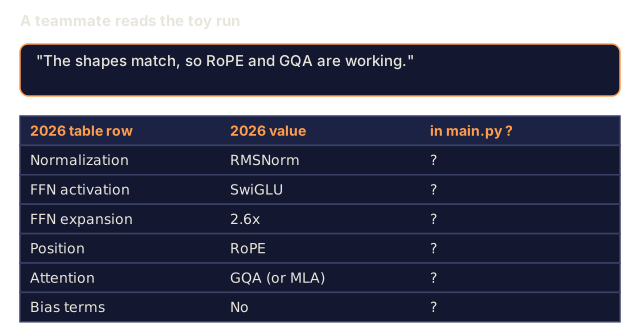
The default stack already uses pre-norm, RMSNorm, and SwiGLU. The one switch in the code is use_swiglu: build BlockParams(..., use_swiglu=False) to get the ReLU FFN and confirm the shapes still match. The norm is hardcoded, so to try LayerNorm, replace the rms_norm calls inside the blocks with layer_norm. RoPE, GQA, and bias handling are not implemented in main.py; the 2026 table above describes them, but the code does not run them.
Use It
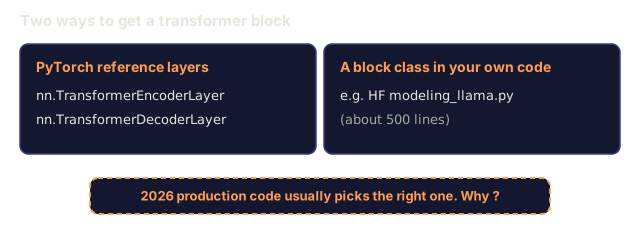
PyTorch and TF ship reference implementations: nn.TransformerEncoderLayer and nn.TransformerDecoderLayer. Most 2026 production code rolls its own block anyway, for three reasons:
- Flash Attention is called inside attention, not through
nn.MultiheadAttention. - GQA and MLA aren't in the stdlib reference.
- RoPE, RMSNorm, and SwiGLU aren't the PyTorch defaults.
HF transformers has clean reference blocks worth reading. modeling_llama.py is the canonical 2026 decoder-only block, about 500 lines, and worth one walkthrough.
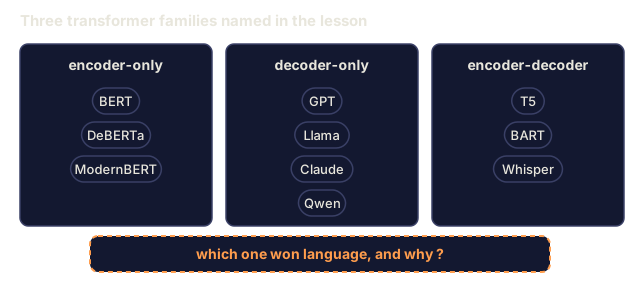
Encoder vs decoder vs encoder-decoder: when to pick which.
| Need | Pick | Example |
|---|---|---|
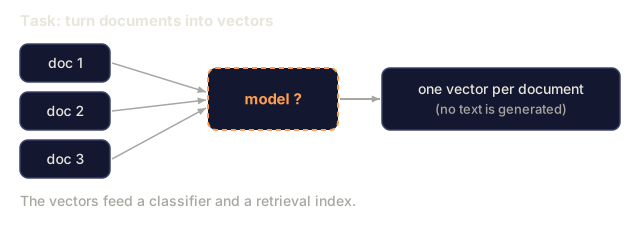
| Classification, embeddings, QA over text | Encoder-only | BERT, DeBERTa, ModernBERT |
| Text generation, chat, code, reasoning | Decoder-only | GPT, Llama, Claude, Qwen |
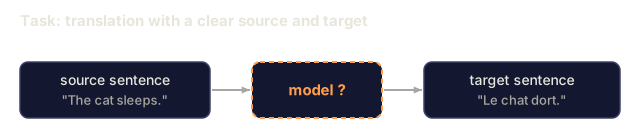
| Structured input → structured output (translation, summarization) | Encoder-decoder | T5, BART, Whisper |
Decoder-only won language because it scales cleanly and handles both comprehension and generation. Encoder-decoder is still the better fit when the input has a clear "source sequence" identity, as in translation, speech recognition, and structured tasks.
Ship It
The skill in outputs/skill-transformer-block-reviewer.md reviews a new transformer block implementation against the 2026 defaults. It flags missing pieces: pre-norm, RoPE, RMSNorm, GQA, and the FFN expansion ratio.
If I'm reviewing someone's block, I check the wiring before the math. Where the norm sits relative to the residual, whether each sublayer has its own residual, and where the cross-attention keys and values come from are the first three things I look at. In main.py the encoder and decoder blocks differ by a causal=True flag and one extra sublayer, which is worth noticing before you open a 500-line production file.
My bet is that the 2026 changes (RMSNorm, SwiGLU, RoPE, GQA) read best as substitutions into the same skeleton, not as a new architecture. In the code, the ReLU FFN and SwiGLU swap behind a single use_swiglu flag and the block wiring doesn't change. I'd run the toy forward pass, confirm shapes, then change one component at a time, so when something looks off you know which swap did it.
I'd also treat the parameter-count formula as a sanity check, not a spec. Re-derive it for your own d and r before you trust any number built on it.
Exercises
- Easy. Count the parameters in a block at
d_model=512, n_heads=8, ffn_expansion=4, swiglu=True, with no biases and no norm scales. By the Parameter count formulas that is4d² + 3·4·d² = 16d²≈ 4.2M for self-attention plus the FFN. Then count the weightsBlockParamsinmain.pyallocates at the same settings: it adds a second set of fourd × dcross-attention matrices, so it holds20d²≈ 5.2M even for an encoder block. Validate both counts by implementing the block and usingsum(p.numel() for p in block.parameters()). - Medium. Switch from post-norm to pre-norm. Initialize both and measure the activation norm after 12 stacked layers on random input. Post-norm's activations should explode; pre-norm's should stay bounded.
- Hard. Implement a 4-layer encoder-decoder on a toy copy task (copy
xreversed). Train 100 steps. Report loss. Swap in RMSNorm + SwiGLU + RoPE. Does loss drop?
Key Terms
| Term | What people say | What it actually means |
|---|---|---|
| Block | "One transformer layer" | Norm + attention + norm + FFN, each sublayer wrapped in a residual connection. |
| Residual | "Skip connection" | The output x + f(x). It lets gradients flow through deep stacks. |
| Pre-norm | "Normalize before, not after" | The modern wiring, x + sublayer(LN(x)). It trains deeper without warmup gymnastics. |
| RMSNorm | "LayerNorm without the mean" | Divide by the RMS. One fewer op, with the same empirical stability. |
| SwiGLU | "The FFN most modern stacks use" | Swish(W1 x) ⊙ W3 x → W2. It beats ReLU/GELU on LM ppl. |
| Cross-attention | "How the decoder sees the encoder" | MHA with Q from the decoder and K/V from the encoder outputs. |
| FFN expansion | "How wide the middle MLP is" | The ratio of hidden size to d_model, usually 4 (LayerNorm) or 2.6 (SwiGLU). |
| Bias-free | "Drop the +b terms" | Modern stacks omit biases in linear layers, for a slight ppl improvement and a smaller model. |
Further Reading
- Vaswani et al. (2017). Attention Is All You Need: original block spec.
- Xiong et al. (2020). On Layer Normalization in the Transformer Architecture: why pre-norm beats post-norm deeply.
- Zhang, Sennrich (2019). Root Mean Square Layer Normalization: RMSNorm.
- Shazeer (2020). GLU Variants Improve Transformer: the SwiGLU paper.
- HuggingFace
modeling_llama.py: canonical 2026 decoder-only block.