BERT — Masked Language Modeling
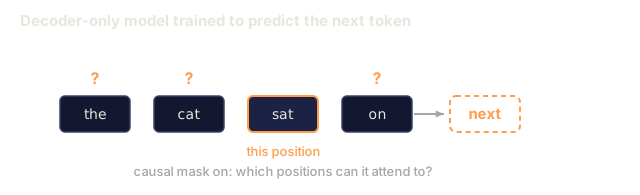
GPT predicts the next word. BERT predicts a missing one. That one-sentence difference gave us half a decade of embedding models.
Learning Objectives
- Explain how masked language modeling trains a bidirectional encoder, and how that differs from next-token prediction.
- Apply the 80/10/10 masking rule and explain why the random and unchanged slices exist.
- Implement MLM masking with -100 labels, skipping special tokens, and check the resulting distribution.
- Describe how a pretrained BERT encoder is adapted for classification, embeddings, and reranking.
- Decide when an encoder such as ModernBERT is the right tool and when a decoder is.
The Problem
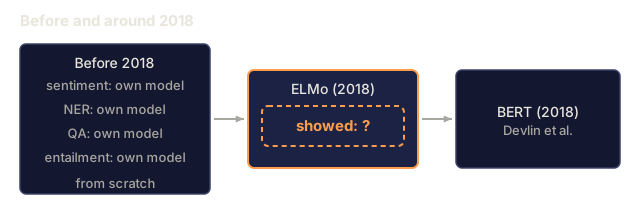
Before 2018, each NLP task (sentiment, NER, QA, entailment) trained its own model from scratch on its own labeled data. There was no pre-trained "understand English" checkpoint to fine-tune. ELMo (2018) showed you could pre-train contextual embeddings with a bidirectional LSTM. It helped but did not generalize.
BERT (Devlin et al. 2018) took a different route: train a transformer encoder on text from across the internet, force it to predict missing words from context on both sides, then fine-tune one head on your downstream task. The parameter efficiency was a revelation.
Within 18 months, BERT and its variants (RoBERTa, ALBERT, ELECTRA) dominated the major NLP leaderboards. By 2020, search engines, content moderation pipelines, and semantic-search systems had a BERT inside.
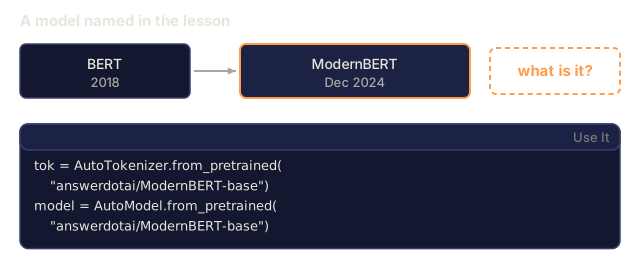
In 2026 encoder-only models are still the right tool for classification, retrieval, and structured extraction. They run 5–10× faster per token than decoders, and their embeddings are the backbone of modern retrieval stacks. ModernBERT (Dec 2024) pushed the architecture to 8K context with Flash Attention, RoPE, and GeGLU.
The Concept

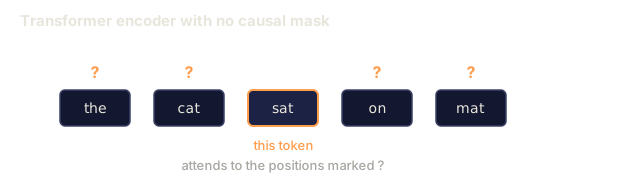
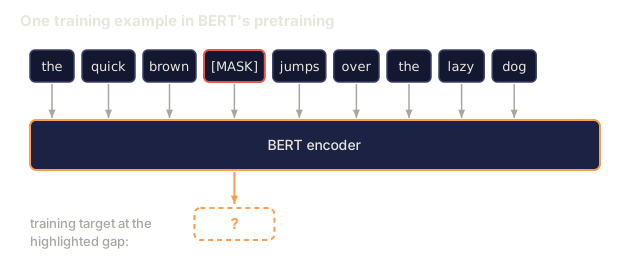
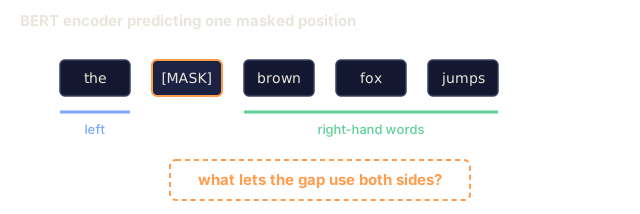
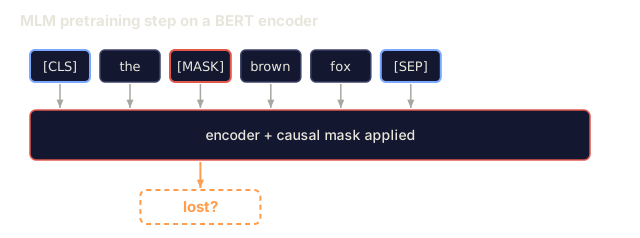
BERT is a transformer encoder pretrained with masked language modeling (MLM): hide some of the input tokens and train the model to recover the originals from the surrounding context. The encoder is bidirectional, so each prediction can draw on the words on both sides of the gap.
The training signal
Take a sentence: the quick brown fox jumps over the lazy dog.
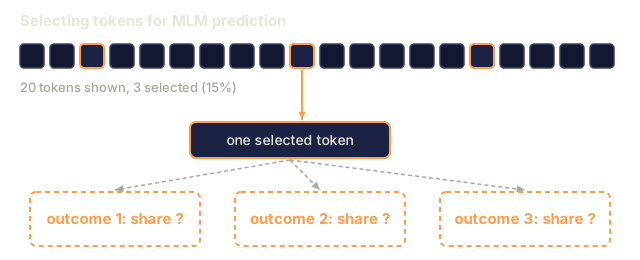
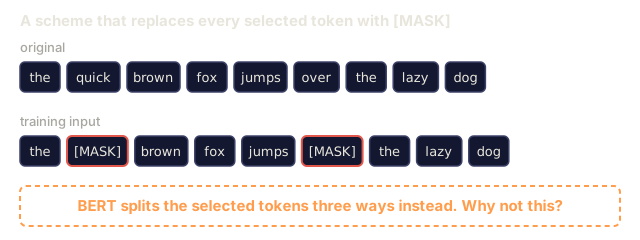
Mask 15% of tokens randomly:
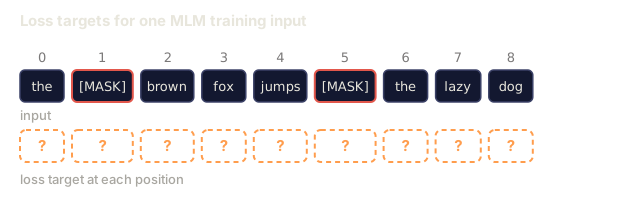
input:  the [MASK] brown fox jumps [MASK] the lazy dog
target: the  quick brown fox jumps  over  the lazy dog
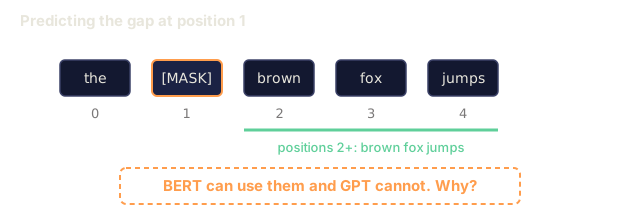
Train the model to predict the original tokens at the masked positions. Predicting [MASK] at position 1 can use brown fox jumps at positions 2+. That is the thing GPT cannot do.
The BERT mask rules
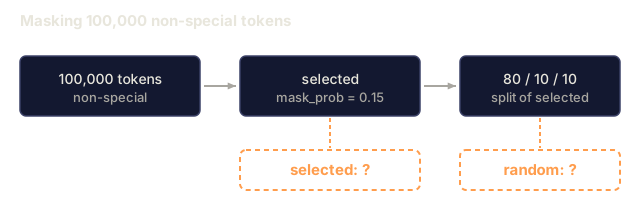
Of the 15% of tokens selected for prediction:
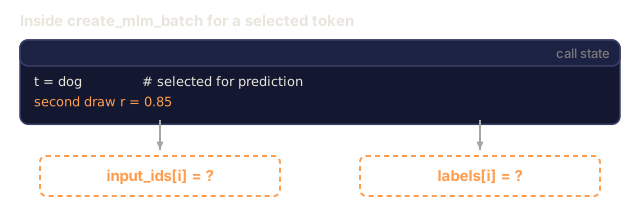
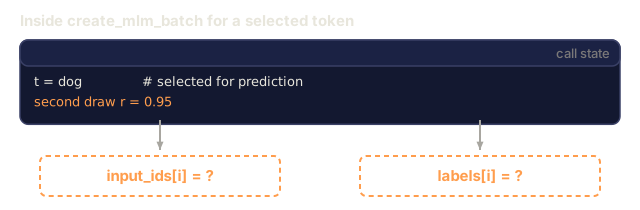
- 80% are replaced with
[MASK]. - 10% are replaced with a random token.
- 10% are left unchanged.
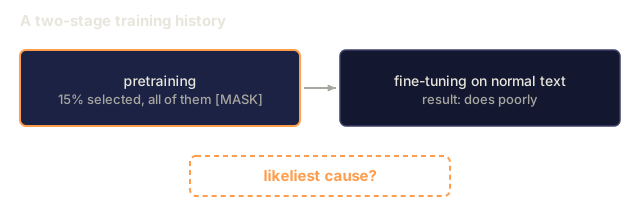
Why not always [MASK]? Because [MASK] never appears at inference time, and training the model to expect it at 100% of masked positions would create a distribution shift between pretraining and fine-tuning. The 10% random and 10% unchanged keep the model honest.
Next Sentence Prediction (NSP), and why it was dropped
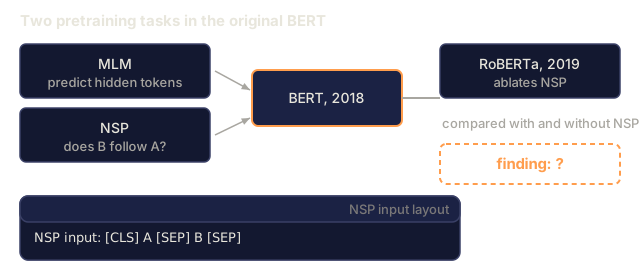
The original BERT also trained on NSP: given two sentences A and B, predict whether B follows A. RoBERTa (2019) ablated it and showed NSP hurt rather than helped. Modern encoders skip it.
What changed in 2026: ModernBERT
The 2024 ModernBERT paper rebuilt the block with current primitives:
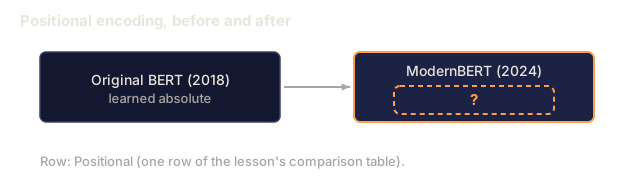
| Component | Original BERT (2018) | ModernBERT (2024) |
|---|---|---|
| Positional | Learned absolute | RoPE |
| Activation | GELU | GeGLU |
| Normalization | LayerNorm | Pre-norm RMSNorm |
| Attention | Full dense | Alternating local (128) + global |
| Context length | 512 | 8192 |
| Tokenizer | WordPiece | BPE |
Unlike the 2018 stack, it is Flash-Attention-native. At sequence length 8K, inference is 2–3× faster than DeBERTa-v3, with better GLUE scores.
Use cases that still pick an encoder in 2026
| Task | Why encoder beats decoder |
|---|---|
| Retrieval / semantic search embeddings | Bidirectional context = better embedding quality per token |
| Classification (sentiment, intent, toxicity) | One forward pass; no generation overhead |
| NER / token labeling | Per-position output, natively bidirectional |
| Zero-shot entailment (NLI) | Classifier head on top of encoder |
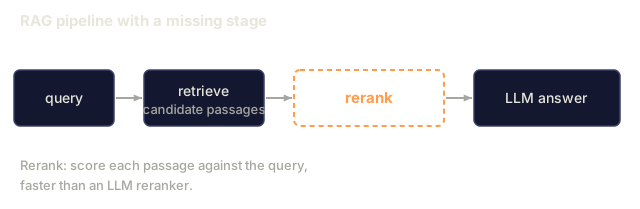
| Reranker for RAG | Cross-encoder scoring, 10x faster than LLM rerankers |
Build It
Step 1: masking logic
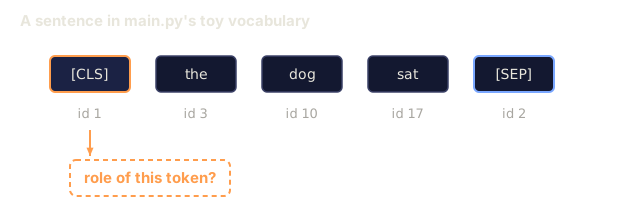
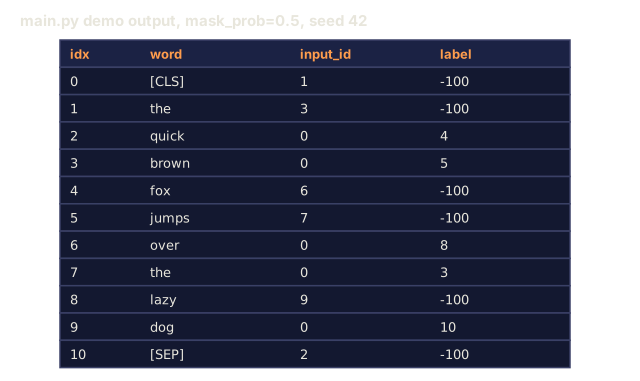
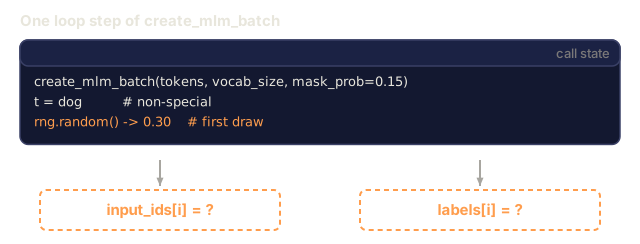
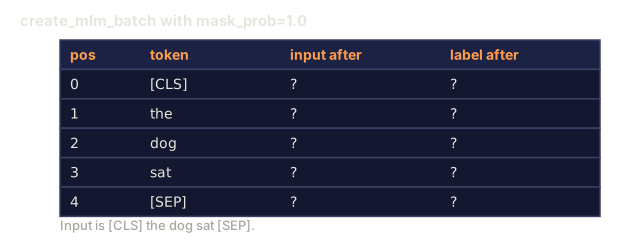
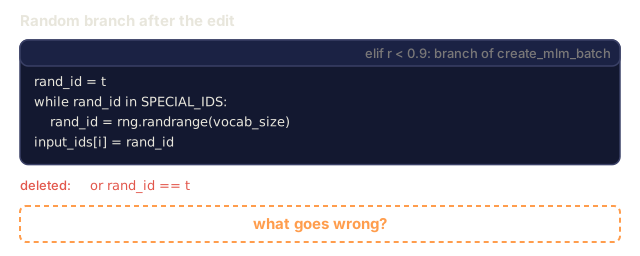
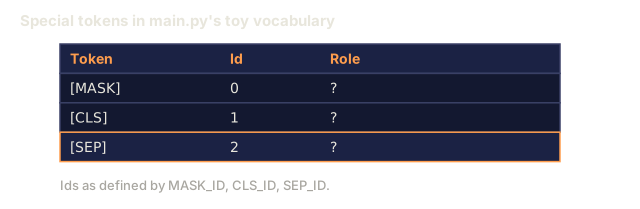
See code/main.py. create_mlm_batch takes a list of token IDs, a vocab size, and a mask probability. It returns input IDs (with masks applied) and labels, which hold the original token at masked positions and -100 everywhere else (PyTorch's ignore-index convention). Special tokens ([MASK], [CLS], [SEP]) are never selected, and a random replacement never picks a special ID or the original token itself. If you pass no rng, it creates a fresh random.Random().
def create_mlm_batch(tokens, vocab_size, mask_prob=0.15, rng=None):
    if rng is None:
        rng = random.Random()
    input_ids = list(tokens)
    labels = [IGNORE_INDEX] * len(tokens)
    for i, t in enumerate(tokens):
        if t in SPECIAL_IDS:
            continue
        if rng.random() >= mask_prob:
            continue
        labels[i] = t
        r = rng.random()
        if r < 0.8:
            input_ids[i] = MASK_ID
        elif r < 0.9:
            rand_id = t
            while rand_id in SPECIAL_IDS or rand_id == t:
                rand_id = rng.randrange(vocab_size)
            input_ids[i] = rand_id
        # else: keep original
    return input_ids, labels
Step 2: run MLM prediction on a tiny corpus
main.py ships the masking logic and a 20-entry toy vocabulary (three special tokens plus 17 words). It has no encoder and no MLM head, so there is no model to run yet. This step is what you build beyond it: a 2-layer encoder plus an MLM head over that vocabulary, fed with sentences you write yourself. There is no gradient step here, only forward-pass sanity checks. Full training needs PyTorch.
Step 3: compare mask types
main.py prints the 80/10/10 shares from distribution_check, but it has no model, so it cannot compare predictions. Once the Step 2 encoder exists, predict on an unmasked sentence and on a masked one. Both should produce reasonable token distributions, because the model saw both patterns in training. That is how you see the three-way rule keeping the model usable without [MASK].
Step 4: fine-tune head
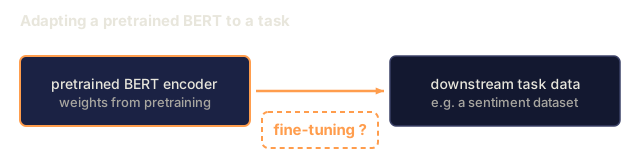
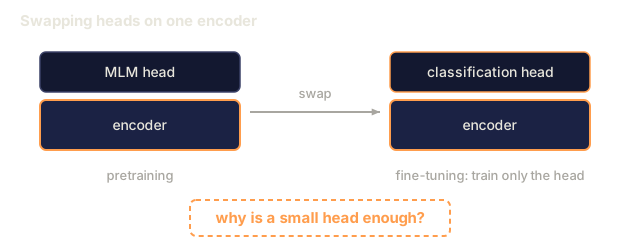
Also beyond main.py: replace the MLM head with a classification head on a toy sentiment dataset. Only the head trains while the encoder stays frozen. This is the basic fine-tuning pattern behind BERT applications (full fine-tuning also updates the encoder, at a small learning rate).
Use It
from transformers import AutoModel, AutoTokenizer

tok = AutoTokenizer.from_pretrained("answerdotai/ModernBERT-base")
model = AutoModel.from_pretrained("answerdotai/ModernBERT-base")

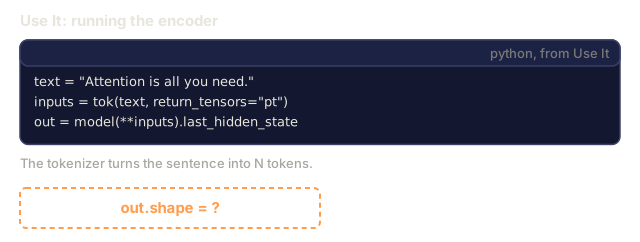
text = "Attention is all you need."
inputs = tok(text, return_tensors="pt")
out = model(**inputs).last_hidden_state   # (1, N, 768)
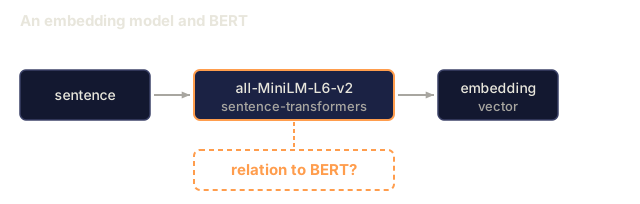
Embedding models are fine-tuned BERT. sentence-transformers models like all-MiniLM-L6-v2 are BERTs trained with contrastive loss. Same encoder, different loss.
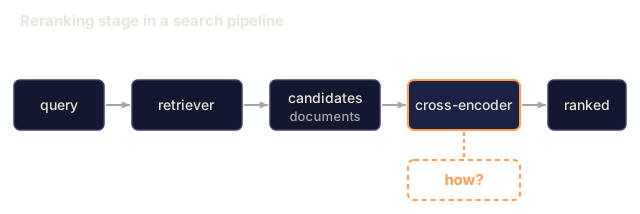
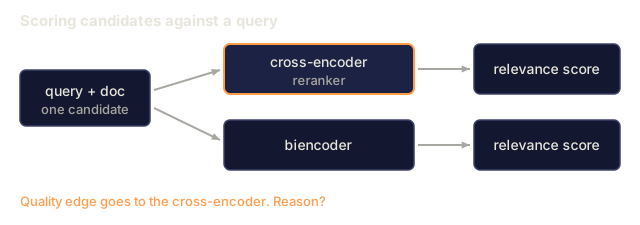
Cross-encoder rerankers are fine-tuned BERT too. They do pair classification on [CLS] query [SEP] doc [SEP]. The bidirectional attention between query and doc is what gives cross-encoders their quality edge over biencoders.
When not to pick BERT in 2026. Anything generative: the encoder has no sensible way to produce tokens autoregressively. Also skip it for anything under 1B params where a small decoder can match quality with more flexibility (Phi-3-Mini, Qwen2-1.5B).
Ship It
See outputs/skill-bert-finetuner.md. The skill scopes a BERT fine-tune for a new classification or extraction task: backbone choice, head spec, data, eval, and stopping.
I'd run Exercise 1 before anything else. The 80/10/10 rule reads like a footnote until you run main.py, which calls distribution_check over 100,000 random tokens and prints the selected, [MASK], random, and unchanged shares next to their targets. Watching the random and unchanged slices sit there as deliberate fractions is a faster way to understand why they exist than rereading the distribution-shift argument.
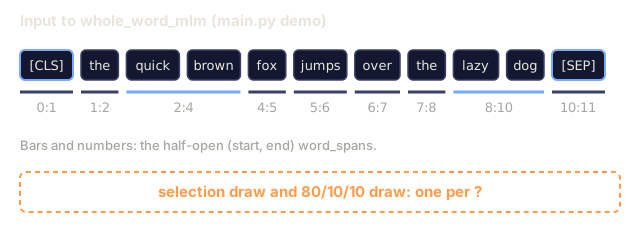
Be careful with the demos, though. toy_predict in main.py returns a uniform distribution, and the script never calls it, so main.py exercises the masking logic and nothing else. The masked-versus-unmasked comparison in Step 3 only means something once a real encoder is behind it. Before you start Exercise 2, read whole_word_mlm in the same file. It makes both the selection draw and the 80/10/10 draw once per word span instead of once per token.
My bet is that the lasting part of BERT is the pattern, not the masking trick: pretrain one encoder, then swap the head or the loss. Embedding models and cross-encoder rerankers both follow it. I'd start from an encoder for classification, retrieval, and reranking, and from a decoder for anything generative.
Exercises
- Easy. Run
code/main.pyand print the mask distribution across 100,000 tokens. Confirm ~15% are selected, and that ~80% of those become[MASK]. - Medium. Extend
whole_word_mlm, which already masks all subwords of a selected word together or none: run a distribution check over its spans likedistribution_checkdoes, then (with an encoder from Step 2) measure whether whole-word masking improves MLM accuracy on a 500-sentence corpus. - Hard. Train a tiny (2-layer, d=64) BERT on 10,000 sentences from a public dataset. Fine-tune the
[CLS]token for SST-2 sentiment. Compare against a decoder-only baseline at matched params. Which wins?
Key Terms
| Term | What people say | What it actually means |
|---|---|---|
| MLM | "Masked language modeling" | Training signal: randomly replace 15% of tokens with [MASK], predict the originals. |
| Bidirectional | "Looks both ways" | Encoder attention has no causal mask, so each position sees every other position. |
[CLS] | "The pooler token" | A special token prepended to a sequence. Its final embedding is used as the sentence-level representation. |
[SEP] | "Segment separator" | Separates paired sequences (e.g. query/doc, sentence A/B). |
| NSP | "Next sentence prediction" | BERT's second pretraining task. RoBERTa showed it was not helping, and it was dropped after 2019. |
| Fine-tuning | "Adapt to a task" | Train a small head on top of the pretrained encoder for the downstream task, with the encoder frozen or only lightly updated. |
| Cross-encoder | "A reranker" | A BERT that takes both query and doc as input and outputs a relevance score. |
| ModernBERT | "2024 refresh" | Encoder rebuilt with RoPE, RMSNorm, GeGLU, alternating local/global attention, 8K context. |
Further Reading
- Devlin et al. (2018). BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding: original paper.
- Liu et al. (2019). RoBERTa: A Robustly Optimized BERT Pretraining Approach: how to train BERT right; kills NSP.
- Clark et al. (2020). ELECTRA: Pre-training Text Encoders as Discriminators Rather Than Generators: replaced-token detection beats MLM at matched compute.
- Warner et al. (2024). Smarter, Better, Faster, Longer: A Modern Bidirectional Encoder: ModernBERT paper.
- HuggingFace
modeling_bert.py: canonical encoder reference.
Code
- main.py (python, 148 lines)