Speaker Recognition & Verification
ASR asks "what did they say?" Speaker recognition asks "who said it?" The math is nearly identical: embeddings plus cosine similarity. Every production decision, though, comes down to a single EER number.
Learning Objectives
- Distinguish speaker verification (1:1) from identification (1:N) and open-set recognition, and state what Equal Error Rate (EER) measures.
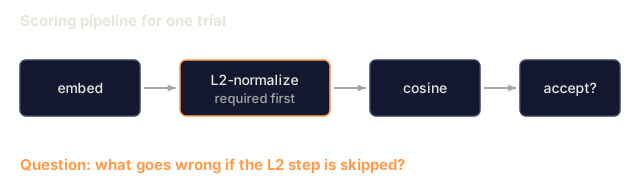
- Build the enroll → embed → cosine-similarity → threshold pipeline, and explain why embeddings must be L2-normalized before scoring.
- Compare x-vector, ECAPA-TDNN, and WavLM-SV on architecture, AAM-softmax training loss, and the speed/accuracy tradeoff, and pick a scoring method (cosine, PLDA, or AS-norm) for a given deployment target.
- Run a diarization pipeline (VAD, segmentation, embedding, clustering) to answer "who spoke when," and read a Diarization Error Rate (DER) figure.
- Avoid the production failure modes covered in this lesson: channel mismatch, short utterances, noisy enrollment, fixed thresholds, and setting a production threshold from EER instead of your own cost of false accepts versus false rejects.
The Problem
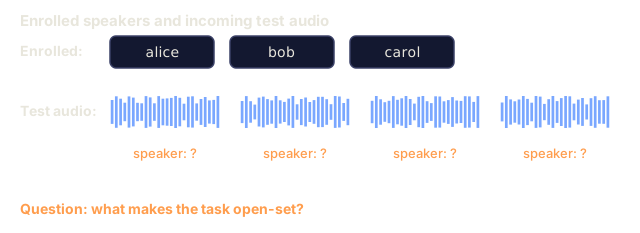
A user says a passphrase. You want to know one of three things: is this the person they claim to be (verification, 1:1)? Is it the first match in your enrollment bank (identification, 1:N)? Or is this someone you've never enrolled at all (open-set)?
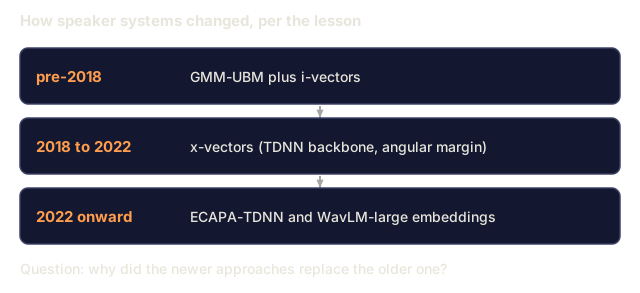
The field got here in three hops. Pre-2018: GMM-UBM plus i-vectors, decent in the lab but fragile to channel shift (phone vs laptop) and emotion. 2018–2022: x-vectors, a TDNN (time-delay neural network) backbone trained with angular margin. 2022 onward: ECAPA-TDNN and WavLM-large embeddings took over. By 2026, three models and one metric dominate everything that matters.
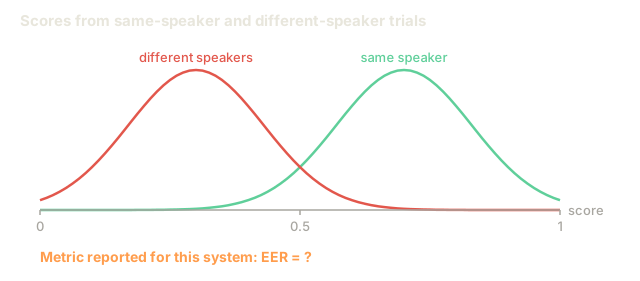
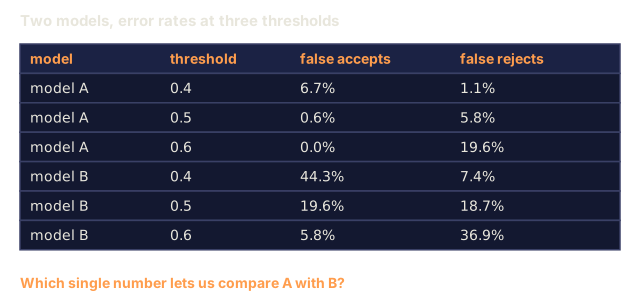
That metric is EER, Equal Error Rate. Set your decision threshold so the False Accept Rate equals the False Reject Rate; the point where those two curves cross is EER. It shows up in every paper, every leaderboard, and every procurement call you'll ever sit through.
The Concept

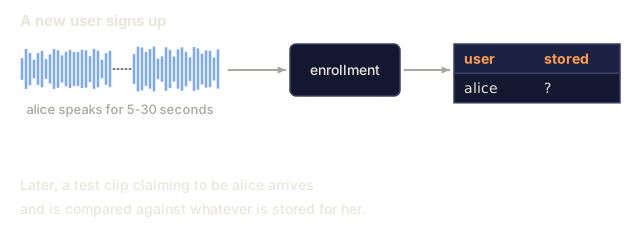
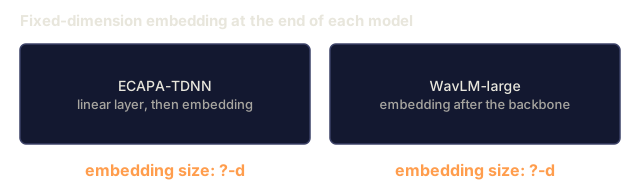
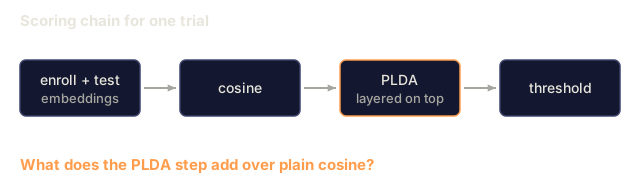
The pipeline. Enrollment: record 5–30 seconds of the target speaker, then compute a fixed-dimension embedding (192-d for ECAPA-TDNN, 256-d for WavLM-large). Verification: embed the test utterance, compute cosine similarity against the enrolled embedding, and compare the result to a threshold.
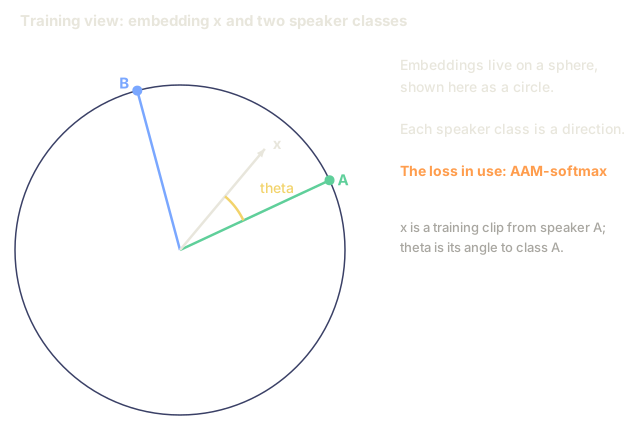
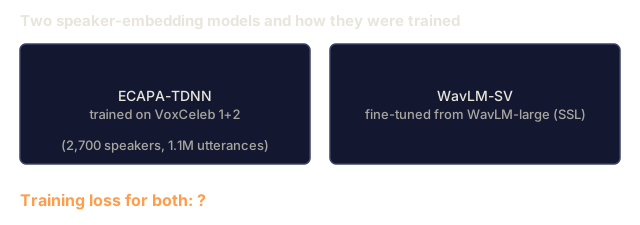
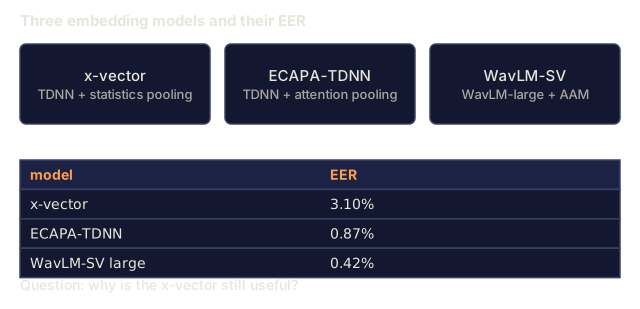
ECAPA-TDNN (2020, still dominant 2026). Emphasized Channel Attention, Propagation and Aggregation - Time-Delay Neural Network. 1D conv blocks with squeeze-excitation, multi-head attention pooling, followed by a linear layer to 192-d. Trained on VoxCeleb 1+2 (2,700 speakers, 1.1M utterances) with Additive Angular Margin loss (AAM-softmax).
WavLM-SV (2022+). Fine-tunes a pretrained WavLM-large SSL (self-supervised learning) backbone with AAM loss. Higher quality, but slower: 300+ MB versus 15 MB.
x-vector (baseline). TDNN plus statistics pooling. The classic approach, and still useful on CPU or at the edge.
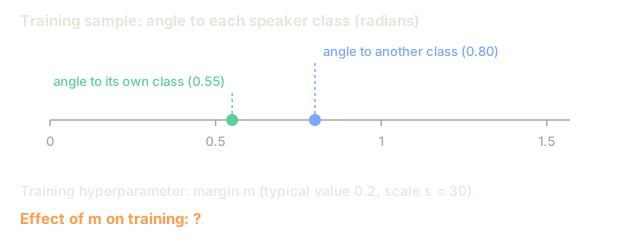
AAM-softmax. Standard softmax with an added margin m in the angular space: cos(θ + m) for the correct class. This forces inter-class angular separation. Typical values are m=0.2 and scale s=30.
Scoring
- Cosine between enrollment and test embeddings. A threshold-based decision, nothing fancier.
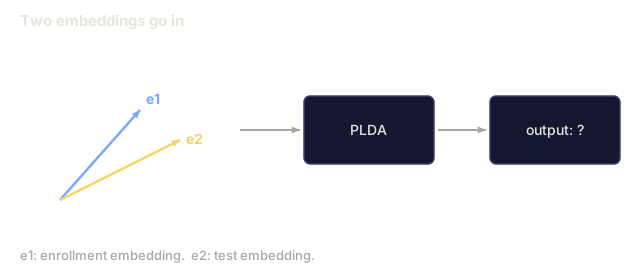
- PLDA (Probabilistic LDA). Projects embeddings into a latent space where same-speaker vs different-speaker has a closed-form likelihood ratio. Layered on top of cosine, it buys a +10–20% EER reduction. Standard before 2020; now used only in closed-set setups.
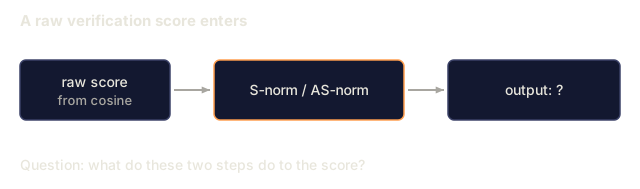
- Score normalization.
S-normorAS-normnormalize each score against a cohort of imposter means and stds, essential once you're evaluating across domains.
Numbers you should know (2026)
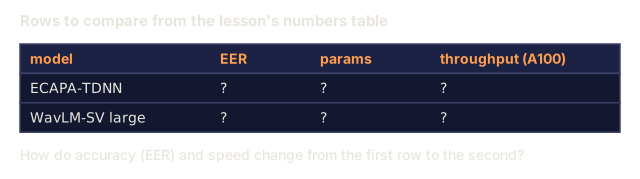
| Model | VoxCeleb1-O EER | Params | Throughput (A100) |
|---|---|---|---|
| x-vector (classic) | 3.10% | 5 M | 400× RT |
| ECAPA-TDNN | 0.87% | 15 M | 200× RT |
| WavLM-SV large | 0.42% | 316 M | 20× RT |
| Pyannote 3.1 segmentation + embedding | 0.65% | 6 M | 100× RT |
| ReDimNet (2024) | 0.39% | 24 M | 100× RT |
Diarization
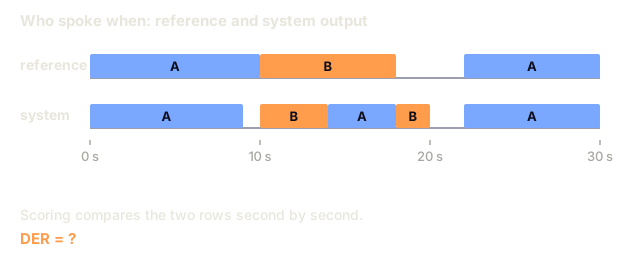
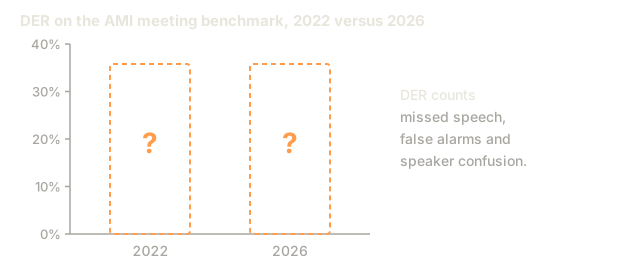
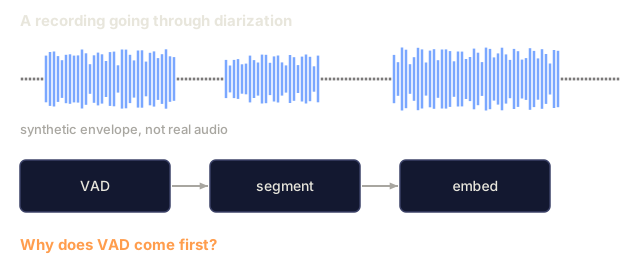
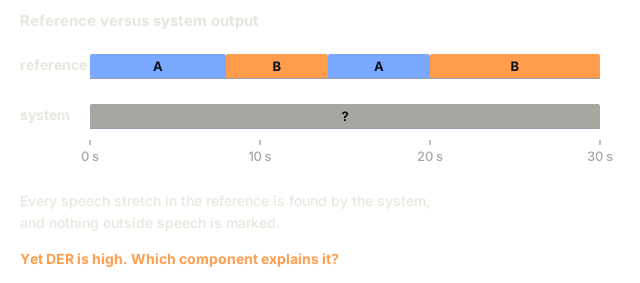
"Who spoke when" in a multi-speaker clip. Pipeline: VAD (voice activity detection, trims silence before anything else runs) → segment → embed each segment → cluster (agglomerative or spectral) → smooth boundaries. The modern stack is pyannote.audio 3.1, which bundles speaker segmentation, embedding, and clustering behind one call. 2026 SOTA DER (Diarization Error Rate: missed speech plus false alarms plus speaker confusion) on the AMI meeting-corpus benchmark sits around 15%, down from 23% in 2022.
Build It
Step 1: toy embedding from MFCC statistics
Before reaching for a pretrained embedder, build the pipeline shape with something you can trace by hand. This toy embedding isn't SOTA by any measure, it exists purely to teach the shape of the pipeline, and code/main.py uses it as a proof of concept on synthetic speaker data.
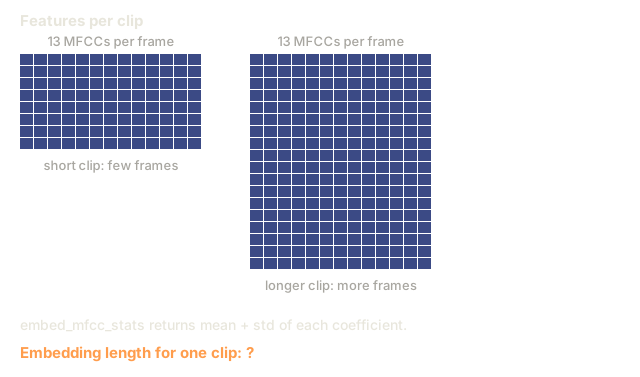
def embed_mfcc_stats(signal, sr):
    frames = featurize_mfcc(signal, sr, n_mfcc=13)
    mean = [sum(f[i] for f in frames) / len(frames) for i in range(13)]
    std = [
        math.sqrt(sum((f[i] - mean[i]) ** 2 for f in frames) / len(frames))
        for i in range(13)
    ]
    return mean + std  # 26-d
Step 2: cosine similarity + threshold
With an enrollment embedding and a test embedding in hand, score how alike they are and turn that score into an accept-or-reject call:
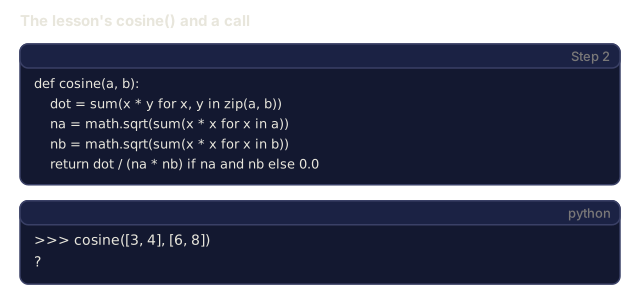
def cosine(a, b):
    dot = sum(x * y for x, y in zip(a, b))
    na = math.sqrt(sum(x * x for x in a))
    nb = math.sqrt(sum(x * x for x in b))
    return dot / (na * nb) if na and nb else 0.0

def verify(enroll, test, threshold=0.75):
    return cosine(enroll, test) >= threshold
Step 3: EER from similarity pairs
Collect same-speaker and different-speaker scores from a trial list, then sweep every possible threshold to find where false accepts and false rejects cross:
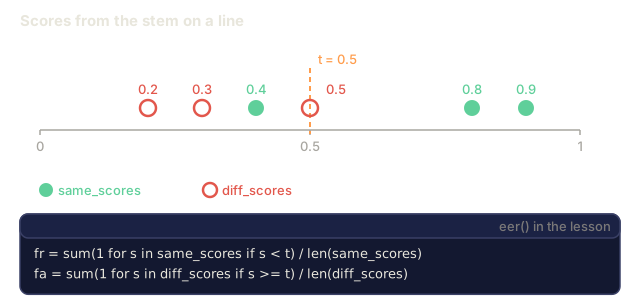
def eer(same_scores, diff_scores):
    thresholds = sorted(set(same_scores + diff_scores))
    best_gap = float("inf")
    best_fa, best_fr, best_t = 1.0, 0.0, thresholds[0] if thresholds else 0.0
    for t in thresholds:
        fr = sum(1 for s in same_scores if s < t) / len(same_scores)
        fa = sum(1 for s in diff_scores if s >= t) / len(diff_scores)
        gap = abs(fa - fr)
        if gap < best_gap:
            best_gap = gap
            best_fa, best_fr, best_t = fa, fr, t
    return (best_fa + best_fr) / 2, best_t
Returns (eer, threshold_at_eer). Report both.
Step 4: production with SpeechBrain
The toy pipeline above proves the shape works. For anything production-bound, swap in a real pretrained embedder instead of hand-rolled MFCC stats:
from speechbrain.pretrained import EncoderClassifier

clf = EncoderClassifier.from_hparams(source="speechbrain/spkrec-ecapa-voxceleb")

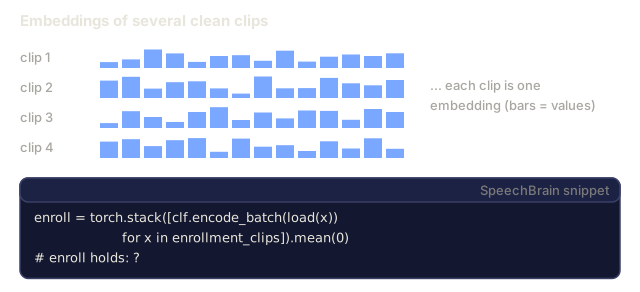
# enroll: average the embeddings of 3-5 clean samples
enroll = torch.stack([clf.encode_batch(load(x)) for x in enrollment_clips]).mean(0)
# verify
score = clf.similarity(enroll, clf.encode_batch(load("test.wav"))).item()
verdict = score > 0.25   # ECAPA typical threshold; tune on your data
Step 5: diarize with pyannote
None of the above helps once a clip has more than one speaker talking at once. For that, reach for a diarization pipeline instead of per-utterance verification:
from pyannote.audio import Pipeline

pipe = Pipeline.from_pretrained("pyannote/speaker-diarization-3.1")
diarization = pipe("meeting.wav", num_speakers=None)
for turn, _, speaker in diarization.itertracks(yield_label=True):
    print(f"{turn.start:.1f}–{turn.end:.1f}  {speaker}")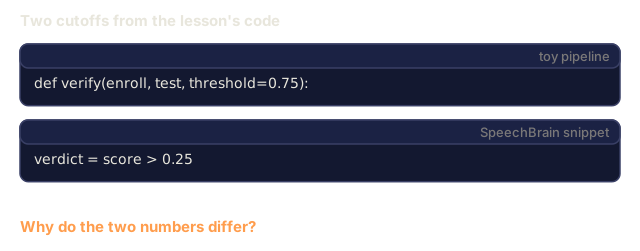
Use It
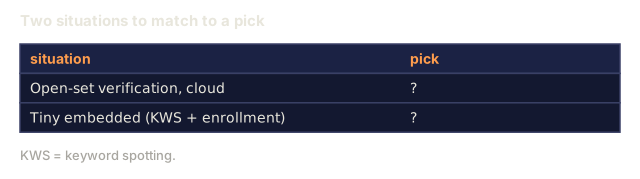
Match the situation to the model. Here's the 2026 stack:
| Situation | Pick |
|---|---|
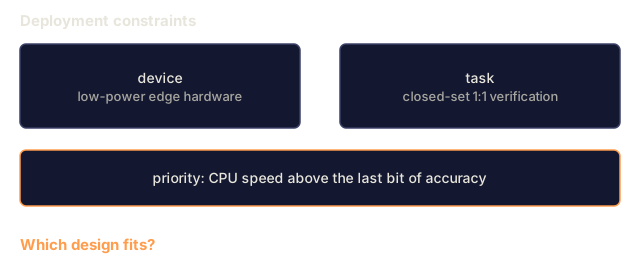
| Closed-set 1:1 verification, edge | ECAPA-TDNN + cosine threshold |
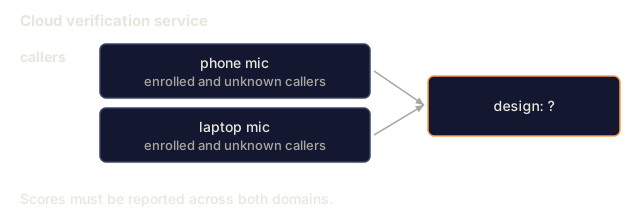
| Open-set verification, cloud | WavLM-SV + AS-norm |
| Diarization (meetings, podcasts) | pyannote/speaker-diarization-3.1 |
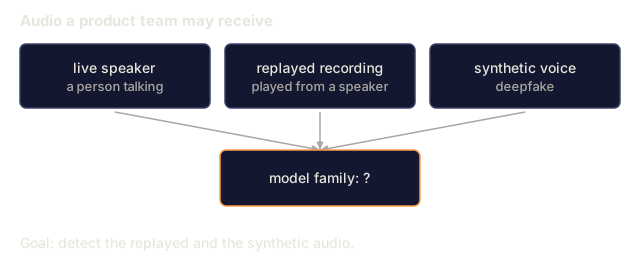
| Anti-spoofing (replay / deepfake detection) | AASIST or RawNet2 |
| Tiny embedded (KWS + enrollment) | Titanet-Small (NeMo) |
Pitfalls
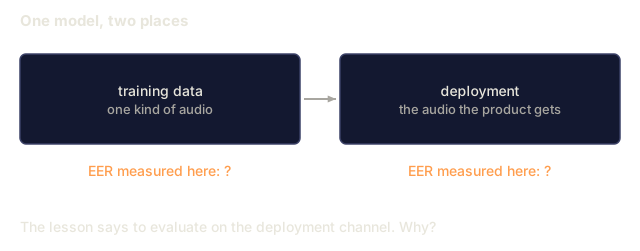
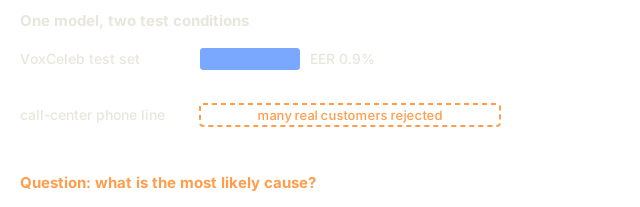
- Channel mismatch. A model trained on VoxCeleb (web video) ≠ phone-call audio. Always evaluate on the channel you'll actually deploy on.
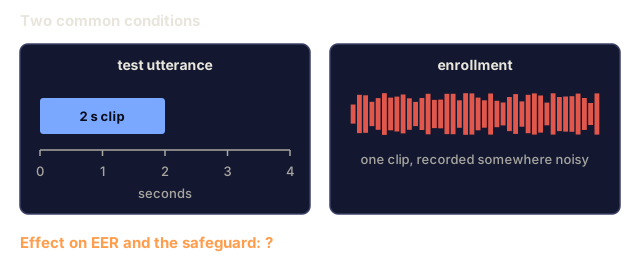
- Short utterances. EER degrades sharply below 3 seconds of test audio.
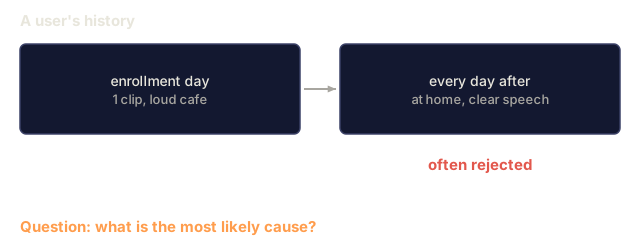
- Enrollment with noise. One noisy enrollment sample poisons the whole anchor. Use ≥3 clean samples and average them.
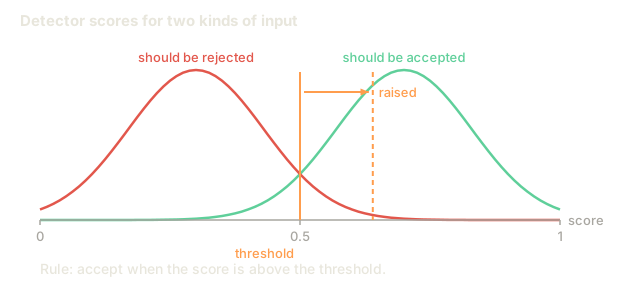
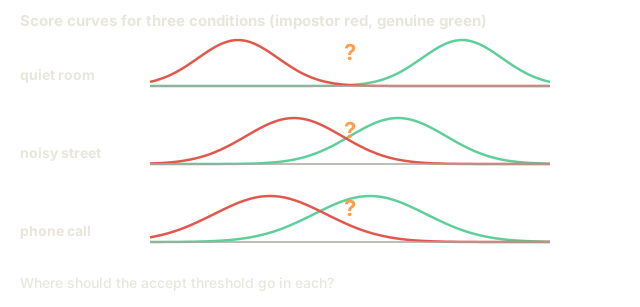
- Fixed threshold across conditions. Always tune the threshold on a held-out dev set drawn from the target domain.
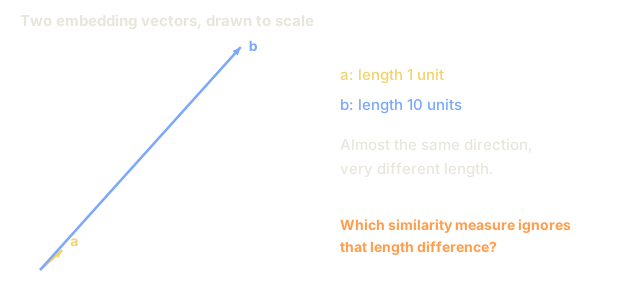
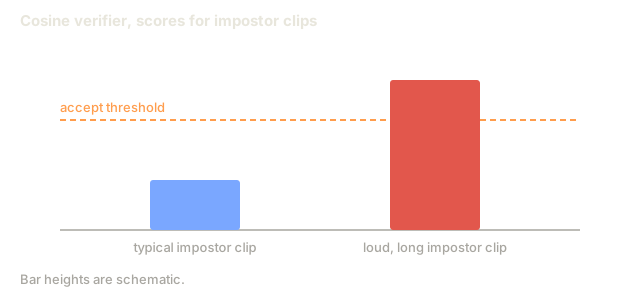
- Cosine on non-normalized embeddings. L2-normalize first, or the magnitude will dominate the score instead of the direction.
Ship It
Save it as outputs/skill-speaker-verifier.md. Nail down the model choice, the enrollment protocol, the threshold-tuning plan, and the fraud safeguards.
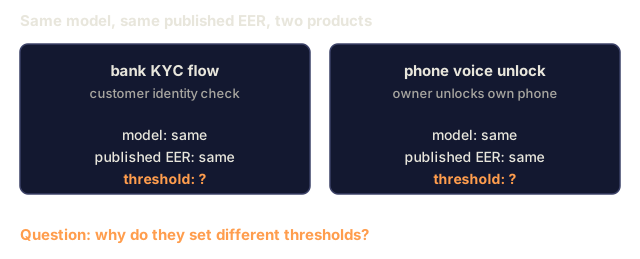
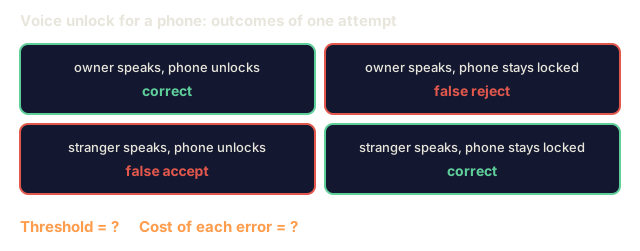
The number every paper reports is EER, but it's rarely the number you should ship. EER is the point where a false accept costs exactly as much as a false reject, and outside of a leaderboard, that's almost never true. Take a banking KYC flow: it would rather turn away ten legitimate customers than let one impostor through, which pushes the threshold well past EER toward zero false accepts, friction and all. A voice-unlock feature on a phone runs the opposite calculation. Annoying the owner every morning costs more than the rare false accept, so the threshold sits lower and the experience stays smooth. Use EER to compare models against each other, not to set your production cutoff. Pick that cutoff from your own cost of a false accept versus a false reject, measured on your own channel, not VoxCeleb's.
Exercises
- Easy. Run
code/main.py. Builds synthetic "speakers" (different tone profiles), enrolls, computes EER on a 100-pair trial list. - Medium. Use SpeechBrain ECAPA on 30 VoxCeleb1 utterances (5 speakers × 6 each). Compute EER with cosine vs PLDA.
- Hard. Build the full enroll → diarize → verify pipeline with
pyannote.audio. Evaluate DER on AMI dev set.
Key Terms
| Term | What people say | What it actually means |
|---|---|---|
| EER | The headline metric | Threshold where False Accept = False Reject. |
| Verification | 1:1 | "Is this Alice?" |
| Identification | 1:N | "Who is speaking?" |
| Open-set | Unknown possible | Test set can contain unenrolled speakers. |
| Enrollment | Registering | Computing a speaker's reference embedding. |
| AAM-softmax | The loss | Softmax with additive angular margin; forces cluster separation. |
| PLDA | Classic scoring | Probabilistic LDA; likelihood-ratio scoring on top of embeddings. |
| DER | Diarization metric | Diarization Error Rate — miss + false alarm + confusion. |
Further Reading
- Snyder et al. (2018). X-Vectors: Robust DNN Embeddings for Speaker Recognition: the classic deep-embedding paper.
- Desplanques et al. (2020). ECAPA-TDNN: the dominant architecture from 2020 to 2026.
- Chen et al. (2022). WavLM: Large-Scale Self-Supervised Pre-Training for Full Stack Speech Processing: the SSL backbone behind SV and diarization.
- Bredin et al. (2023). pyannote.audio 3.1: the production diarization plus embedding stack.
- VoxCeleb leaderboard (updated 2026): current EER standings across models.
Code
- main.py (python, 198 lines)