Audio Evaluation — WER, MOS, UTMOS, MMAU, FAD, and the Open Leaderboards
You cannot ship what you cannot measure. This lesson names the 2026 metrics for every audio task: ASR (WER, CER, RTFx), TTS (MOS, UTMOS, SECS, WER-on-ASR-round-trip), audio-language (MMAU, LongAudioBench), music (FAD, CLAP), and speaker (EER). Plus the leaderboards where you compare.
Learning Objectives
- Name the primary and secondary evaluation metric for every audio task in this lesson: ASR, TTS, voice cloning, speaker verification, diarization, classification, music generation, audio-language models, and streaming speech-to-speech.
- Compute WER, round-trip WER, SECS, EER, and FAD in code, and explain what each score actually measures.
- Explain why a single aggregate number, like overall WER or MOS, can hide real failures, and report results as distributions and per-slice breakdowns instead.
- Find the right 2026 leaderboard for a given audio task and use it to benchmark a model release against the field.
The Problem
Every audio task comes with a handful of metrics, and each one measures a different axis of quality. Pick the wrong one and you'll ship a model that looks great on your dashboard and terrible in production. Here's the 2026 canonical list, task by task:
| Task | Primary | Secondary |
|---|---|---|
| ASR | WER | CER · RTFx · first-token latency |
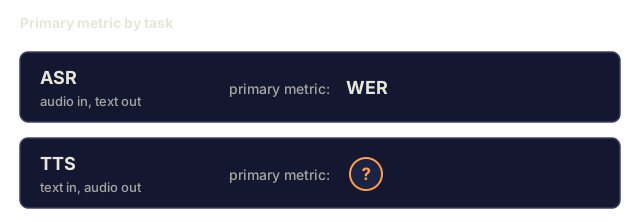
| TTS | MOS / UTMOS | SECS · WER-on-ASR-round-trip · CER · TTFA |
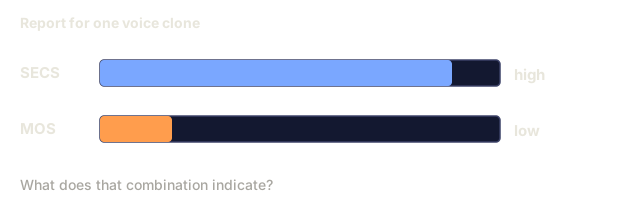
| Voice cloning | SECS (ECAPA cosine) | MOS · CER |
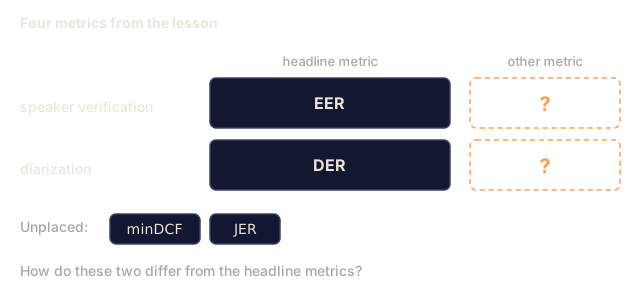
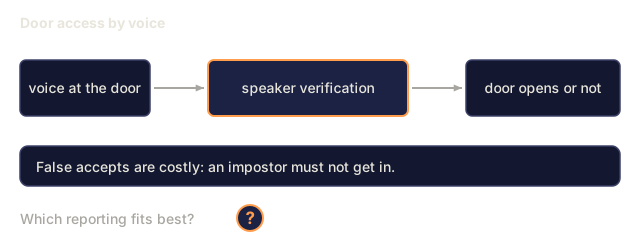
| Speaker verification | EER | minDCF · FAR / FRR at operating point |
| Diarization | DER | JER · speaker confusion |
| Audio classification | top-1 · mAP | macro F1 · per-class recall |
| Music generation | FAD | CLAP · listening panel MOS |
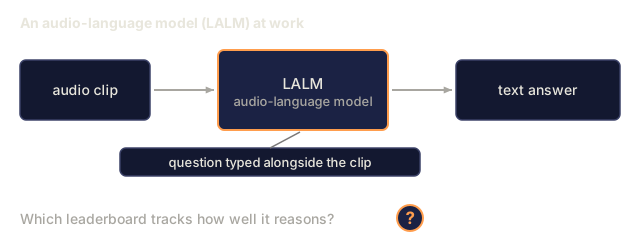
| Audio language model | MMAU-Pro | LongAudioBench · AudioCaps FENSE |
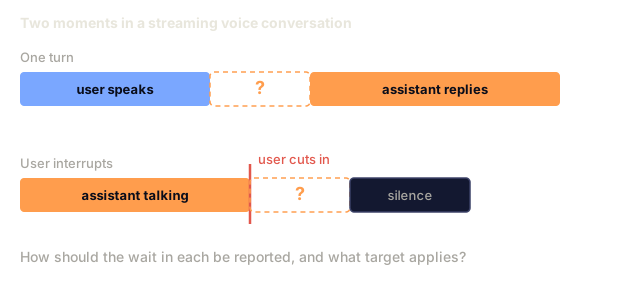
| Streaming S2S | latency P50/P95 | WER · MOS |
The Concept

ASR metrics
WER and CER both answer the same question: how many words, or characters, did the model get wrong. RTFx and first-token latency measure something different, how fast the model produces an answer at all.
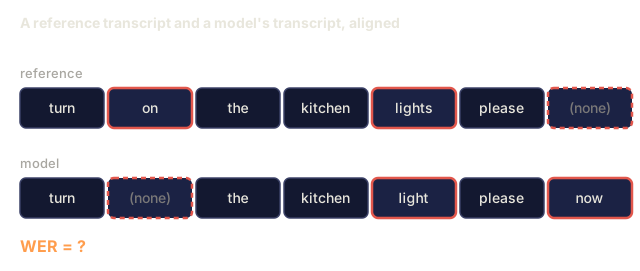
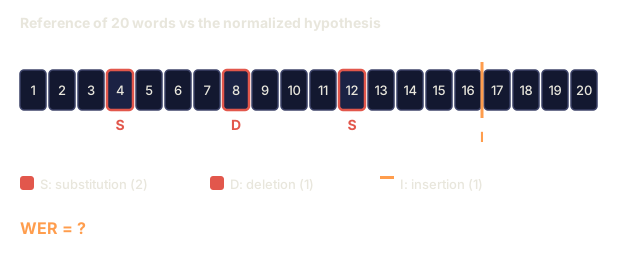
WER (Word Error Rate). (S + D + I) / N. Lowercase, strip punctuation, normalize numbers before scoring. Use jiwer or OpenAI's whisper_normalizer. < 5% = human-parity read speech.
CER (Character Error Rate). Same formula, character-level. Used for tone languages (Mandarin, Cantonese) where word segmentation is ambiguous.
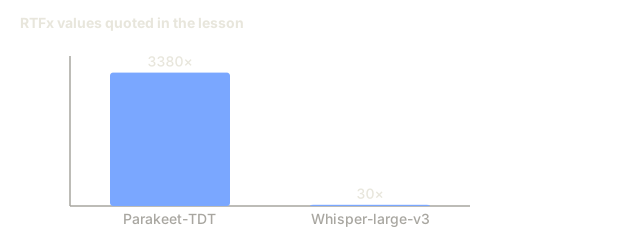
RTFx (inverse real-time factor). Audio seconds processed per wall-clock second. Higher is better. Parakeet-TDT hits 3380×. Whisper-large-v3 is ~30×.
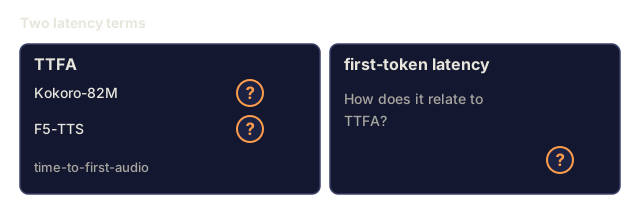
First-token latency. Wall-clock from audio input to first transcript token. Critical for streaming. Deepgram Nova-3: ~150 ms.
TTS metrics
TTS splits that question in two: does it sound like a person, and does it say the right words?
MOS (Mean Opinion Score). 1-5 human rating. Gold standard but slow. Collect 20+ listeners per sample, 100+ samples per model.
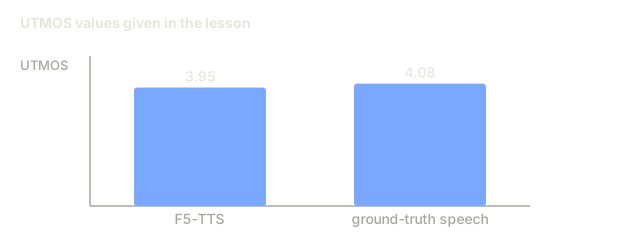
UTMOS (2022-2026). Learned MOS predictor. Correlates ~0.9 with human MOS on standard benchmarks. F5-TTS: UTMOS 3.95; ground truth: 4.08.
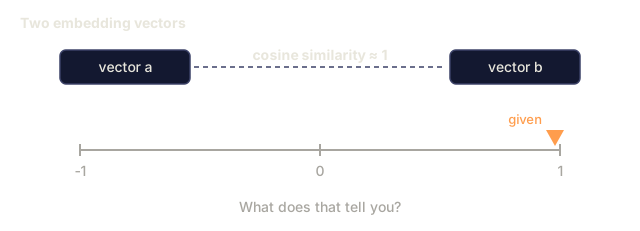
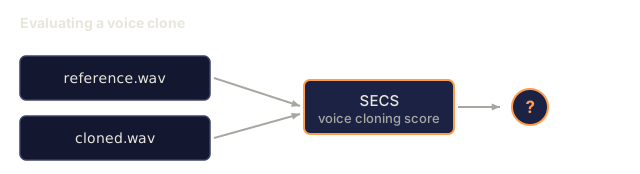
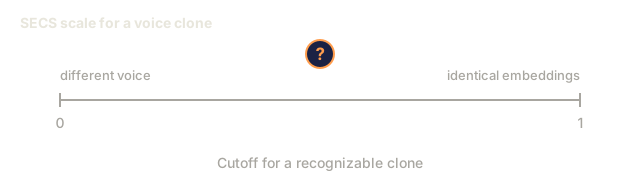
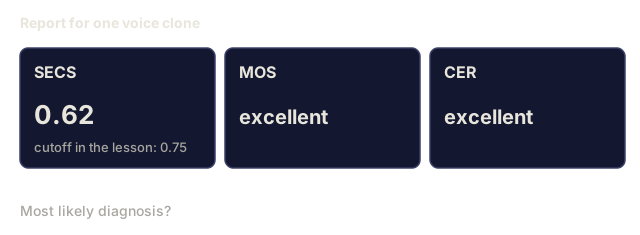
SECS (Speaker Encoder Cosine Similarity). For voice cloning. ECAPA embedding cosine between reference and cloned output. > 0.75 = recognizable clone.
WER-on-ASR-round-trip. Run Whisper over TTS output, compute WER against the input text. Catches intelligibility regressions. 2026 SOTA: < 2% CER.
TTFA (time-to-first-audio). Wall-clock latency. Kokoro-82M: ~100 ms; F5-TTS: ~1 s.
Voice-cloning-specific
Run SECS, MOS, and CER together, as a triple, not one at a time. A clone that scores high SECS but low MOS nailed the timbre and lost the naturalness. Flip those two scores and you get the opposite problem: a natural voice that isn't the speaker you asked for.
Speaker verification
Speaker verification asks a binary question: same voice, or not?
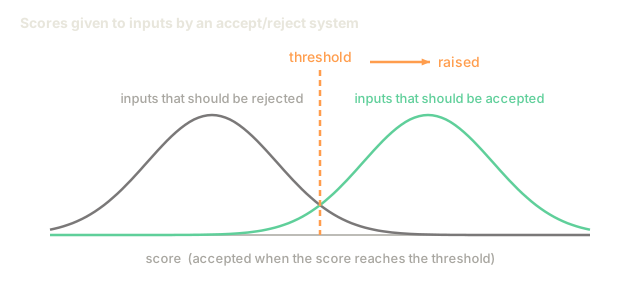
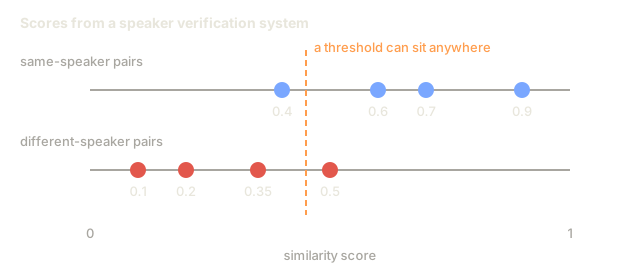
EER (Equal Error Rate). The threshold where False Accept Rate equals False Reject Rate. ECAPA on VoxCeleb1-O: 0.87%.
minDCF (min Detection Cost). Weighted cost at a chosen operating point (often FAR=0.01). More production-relevant than EER.
Diarization
Diarization tracks when each speaker is talking, not just who's in the room.
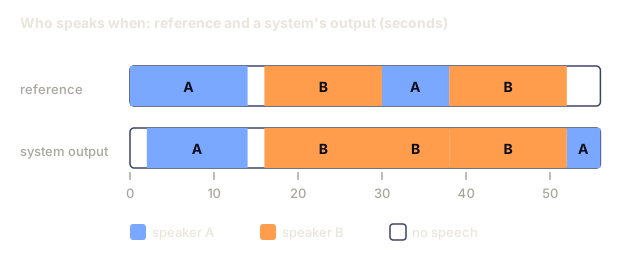
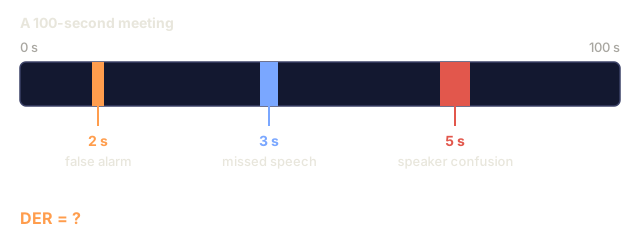
DER (Diarization Error Rate). (FA + Miss + Confusion) / total_speaker_time. Missed speech, false-alarm speech, and speaker-confusion, each counted as a fraction. AMI meetings: DER ~10-20% is realistic. pyannote 3.1 + Precision-2 commercial: <10% DER on well-recorded audio.
JER (Jaccard Error Rate). Alternative to DER, robust to short-segment bias.
Audio classification
Which metric fits depends on the shape of the task, not the audio itself.
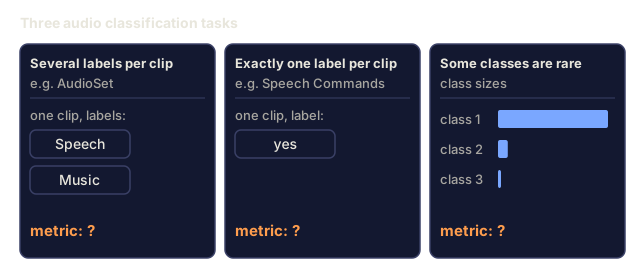
Multi-label: mAP (mean Average Precision) over all classes. AudioSet: 0.548 mAP for BEATs-iter3.
Multi-class exclusive: top-1, top-5 accuracy. Speech Commands v2: 99.0% top-1 (Audio-MAE).
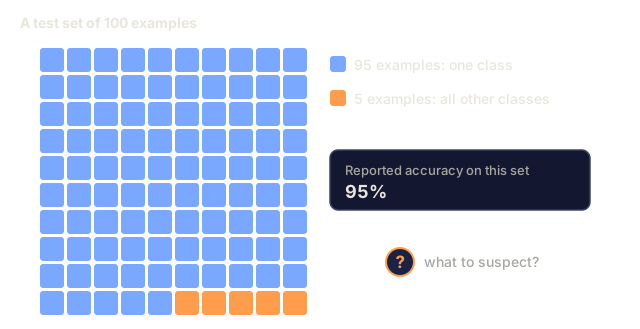
Imbalanced: macro F1 plus per-class recall. Report per-class: an aggregate accuracy number hides exactly which classes are failing.
Music generation
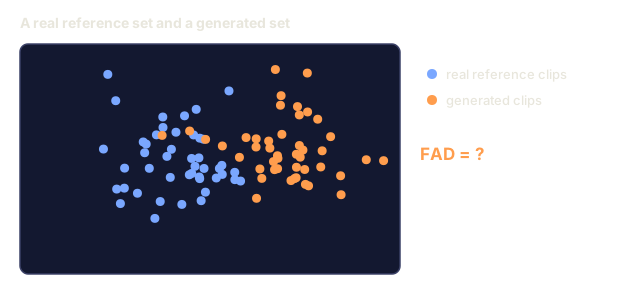
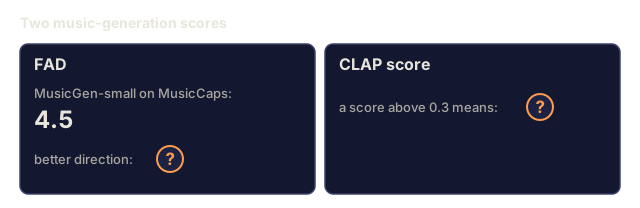
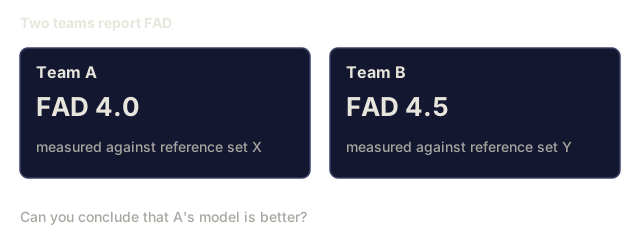
FAD (Fréchet Audio Distance). Distance between VGGish-embedding distributions of real vs generated audio. MusicGen-small on MusicCaps: 4.5. MusicLM: 4.0. Lower is better.
CLAP Score. Text-audio alignment score using CLAP embeddings. > 0.3 = reasonable alignment.
Listening panel MOS. Still the final word for consumer-grade music. Suno v5 ELO 1293 on TTS Arena (from paired human preferences).
Audio-language benchmarks
This is where 2026 audio-language models still look weakest, especially once a question spans more than one clip.
MMAU (Massive Multi-Audio Understanding). 10k audio-QA pairs.
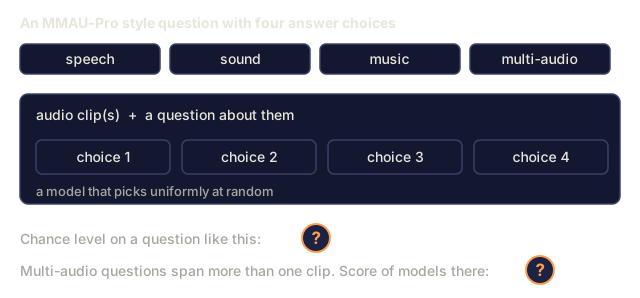
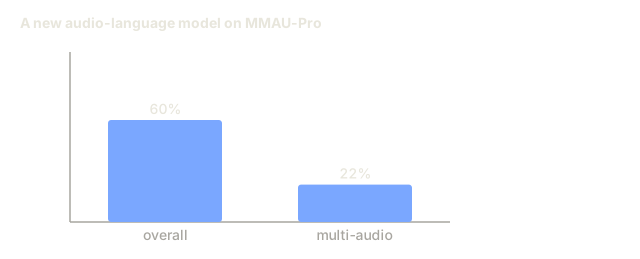
MMAU-Pro. 1800 hard items, four categories: speech / sound / music / multi-audio. Random chance is 25% on 4-way questions. Gemini 2.5 Pro's overall score is about 60%, but multi-audio sits at about 22% across every model tested.
LongAudioBench. Multi-minute clips with semantic queries. Audio Flamingo Next beats Gemini 2.5 Pro.
AudioCaps / Clotho. Captioning benchmarks. SPICE, CIDEr, FENSE metrics.
Streaming speech-to-speech
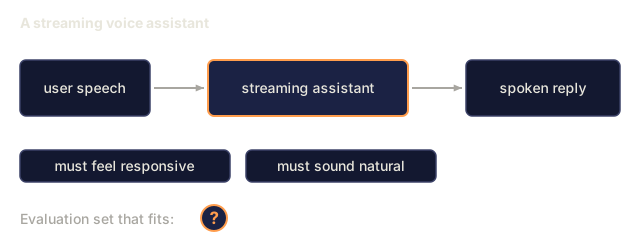
For a streaming system, latency is the metric that decides whether it feels alive or laggy.
Latency P50 / P95 / P99. Wall-clock from end-of-user-speech to first audible response. Moshi: 200 ms; GPT-4o Realtime: 300 ms.
WER / MOS on the output.
Barge-in responsiveness. Time from user interrupt to assistant mute. Target < 150 ms.
The 2026 leaderboards
Every metric above needs somewhere to compare against. These are the boards that matter in 2026:
| Leaderboard | Tracks | URL |
|---|---|---|
| Open ASR Leaderboard (HF) | English + multilingual + long-form | huggingface.co/spaces/hf-audio/open_asr_leaderboard |
| TTS Arena (HF) | English TTS | huggingface.co/spaces/TTS-AGI/TTS-Arena |
| Artificial Analysis Speech | TTS + STT, ELO from paired votes | artificialanalysis.ai/speech |
| MMAU-Pro | LALM reasoning | mmaubenchmark.github.io |
| SpeakerBench / VoxSRC | Speaker recognition | voxsrc.github.io |
| MMAU music subset | Music LALM | (within MMAU) |
| HEAR benchmark | Self-supervised audio | hearbenchmark.com |
Build It
Five short scripts, one metric each. Wire these into your eval harness once and reuse every one of them for the next model release.
Step 1: WER with normalization
Normalize before you score anything, or you're measuring casing and punctuation instead of real errors.
from jiwer import wer, Compose, ToLowerCase, RemovePunctuation, Strip

transform = Compose([ToLowerCase(), RemovePunctuation(), Strip()])
score = wer(
    truth="Please turn on the lights.",
    hypothesis="please turn on the light",
    truth_transform=transform,
    hypothesis_transform=transform,
)
# 0.20 (1 substitution / 5 reference words)
Step 2: TTS round-trip WER
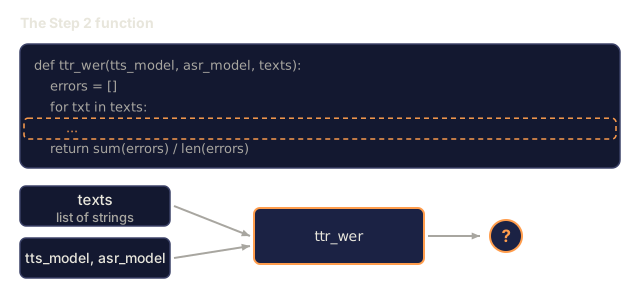
No human listener needed. Synthesize the text, transcribe it back with an ASR model, and score the round trip against the original.
def ttr_wer(tts_model, asr_model, texts):
    errors = []
    for txt in texts:
        audio = tts_model.synthesize(txt)
        recog = asr_model.transcribe(audio)
        errors.append(wer(truth=txt, hypothesis=recog))
    return sum(errors) / len(errors)
Step 3: SECS for voice cloning
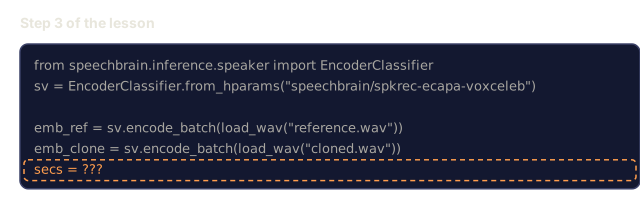
Encode both clips with the same speaker model and take the cosine similarity between the two embeddings.
from speechbrain.inference.speaker import EncoderClassifier
sv = EncoderClassifier.from_hparams("speechbrain/spkrec-ecapa-voxceleb")

emb_ref = sv.encode_batch(load_wav("reference.wav"))
emb_clone = sv.encode_batch(load_wav("cloned.wav"))
secs = torch.nn.functional.cosine_similarity(emb_ref, emb_clone, dim=-1).item()
Step 4: FAD for music generation
There's no transcript to check here, so FAD compares distributions instead: how close a whole batch of generated audio sits to a batch of real audio.
from frechet_audio_distance import FrechetAudioDistance
fad = FrechetAudioDistance()
score = fad.get_fad_score("generated_folder/", "reference_folder/")
Step 5: EER for speaker verification (same code as Lesson 6)
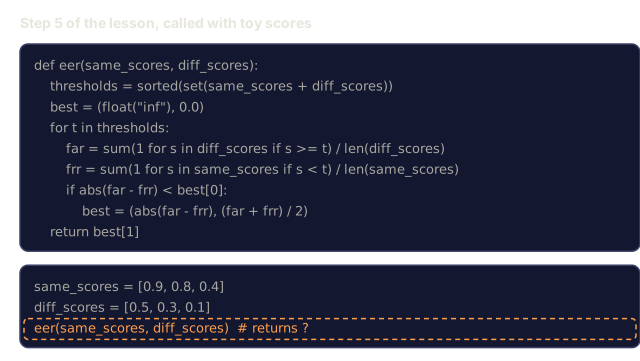
Same threshold sweep you already used for speaker verification: find the point where false accepts and false rejects cross.
def eer(same_scores, diff_scores):
    thresholds = sorted(set(same_scores + diff_scores))
    best = (float("inf"), 0.0)
    for t in thresholds:
        far = sum(1 for s in diff_scores if s >= t) / len(diff_scores)
        frr = sum(1 for s in same_scores if s < t) / len(same_scores)
        if abs(far - frr) < best[0]:
            best = (abs(far - frr), (far + frr) / 2)
    return best[1]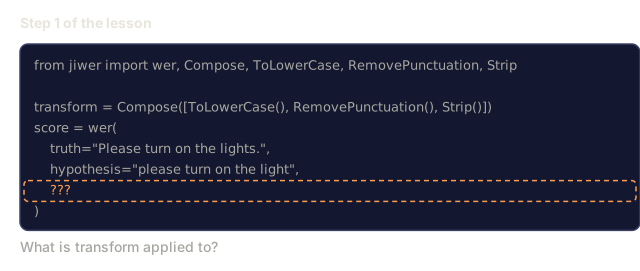
Use It
Pair every deploy with a fixed eval harness that runs on every model update, no exceptions. Three rules govern how you report the results:
- Normalize before scoring. Lowercase, punctuation-strip, number-expand, and report the normalization rule you used.
- Report distributions, not averages. P50/P95/P99 for latency, per-class recall for classification, per-category for MMAU.
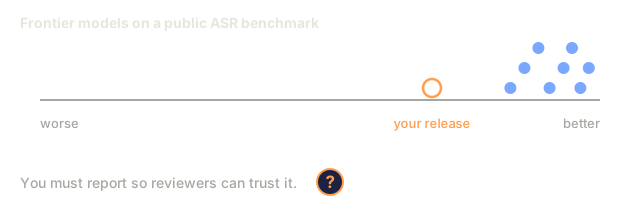
- Run one canonical public benchmark. Your production data will look different from the benchmark's, but reporting on Open ASR, TTS Arena, or MMAU is what lets reviewers compare your numbers apples-to-apples with everyone else's.
Pitfalls
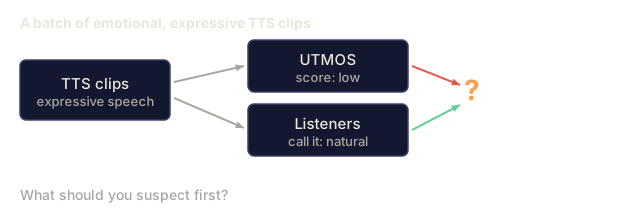
- UTMOS extrapolation. It's trained on VCTK-style clean speech, so it scores noisy, cloned, or emotional audio poorly.
- MOS panel bias. Twenty Amazon Mechanical Turk workers aren't twenty target users. Pay for a domain panel if the stakes are high.
- FAD depends on the reference set. Compare every model against the same reference distribution, or the numbers won't mean anything next to each other.
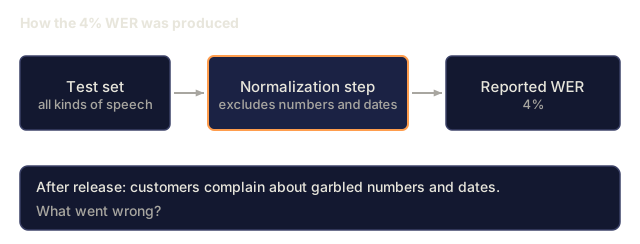
- Aggregate WER. A 5% overall WER can hide a 30% WER on accented speech. Report by demographic slice.
- Public benchmark saturation. Most frontier models already sit near the ceiling on standard benchmarks. Build an in-house held-out set that actually reflects your traffic.
Ship It
Save this as outputs/skill-audio-evaluator.md: a reference for picking metrics, benchmarks, and a reporting format for any audio model you ship.
The failure mode I see most with audio evaluation isn't picking the wrong metric. It's picking one metric and defending it long after it stopped telling you anything useful. A team ships a 4% WER model, throws a party, then finds out customers are furious about garbled numbers and dates — exactly the slice their number-normalization step was quietly excluding from the count. Every metric on this page has a blind spot like that: UTMOS goes soft on anything that isn't clean read speech, FAD only means something relative to whatever reference set you picked, and one aggregate WER number hides exactly which accent your model is actually failing on.
No single smarter metric fixes that. What works is running several of them against a slice that looks like your real traffic, and staying suspicious of any number that only ever goes up.
Exercises
- Easy. Run
code/main.py. Compute WER / CER / EER / SECS / FAD-ish / MMAU-ish on toy inputs. - Medium. Build a TTS round-trip WER harness. Run your Kokoro or F5-TTS output through Whisper. Compute WER over 50 prompts. Flag prompts with WER > 10%.
- Hard. Score your Lesson 10 LALM choice on MMAU-Pro speech + multi-audio subsets (50 items each). Report per-category accuracy and compare with the published number.
Key Terms
| Term | What people say | What it actually means |
|---|---|---|
| WER | ASR score | (S+D+I)/N at word level after normalization. |
| CER | Character WER | For tone languages or char-level systems. |
| MOS | Human opinion | 1-5 rating; 20+ listeners × 100 samples. |
| UTMOS | ML MOS predictor | Learned model; correlates ~0.9 with human MOS. |
| SECS | Voice-clone similarity | ECAPA cosine between reference and clone. |
| EER | Speaker verif score | Threshold where FAR = FRR. |
| DER | Diarization score | (FA + Miss + Confusion) / total. |
| FAD | Music-gen quality | Fréchet distance on VGGish embeddings. |
| RTFx | Throughput | Audio seconds per wall-clock second. |
Further Reading
- jiwer: WER/CER library with normalization utilities.
- UTMOS (Saeki et al. 2022): learned MOS predictor.
- Fréchet Audio Distance (Kilgour et al. 2019): the music-gen standard.
- Open ASR Leaderboard: 2026 live rankings.
- TTS Arena: human-vote TTS leaderboard.
- MMAU-Pro benchmark: LALM reasoning leaderboard.
- HEAR benchmark: audio SSL benchmarks.
Code
- main.py (python, 151 lines)