Text-to-Speech (TTS) — From Tacotron to F5 and Kokoro
ASR inverts speech to text; TTS inverts text to speech. The 2026 stack is three parts: text → tokens, tokens → mel, mel → waveform. Each part has a default model that fits in a laptop.
Learning Objectives
- Break the TTS pipeline into its three stages: text frontend, acoustic model, and vocoder, and identify which stage produced a given failure
- Name the major TTS acoustic models (Tacotron 2, FastSpeech 2, VITS, F5-TTS, Kokoro) and explain the core architectural tradeoff each one makes
- Implement a full TTS pipeline in code: phonemize text, synthesize speech with Kokoro and with F5-TTS voice cloning, and connect a vocoder to turn mel spectrograms into audio
- Pick the right evaluation metric for a TTS system (MOS, CMOS, UTMOS/DNSMOS, CER via ASR, SECS) and avoid the pipeline's most common production pitfalls
The Problem
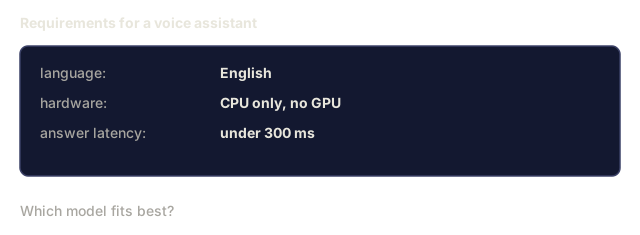
You have a string: "Please remind me to water the plants at 6 pm." You need a 3-second clip that sounds natural, gets the prosody right (pauses, stress), pronounces "plants" with the correct vowel, and runs in under 300 ms on a CPU inside a live voice assistant. You also need to swap voices on demand and not embarrass yourself on someone's name. Code-switched input ("remind me at 6 pm, daijoubu?") is a real production headache too, but multilingual phonemization is its own problem, out of scope here.
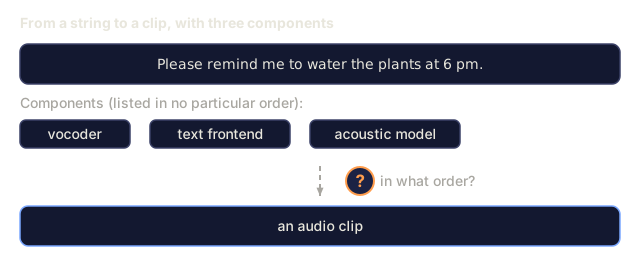
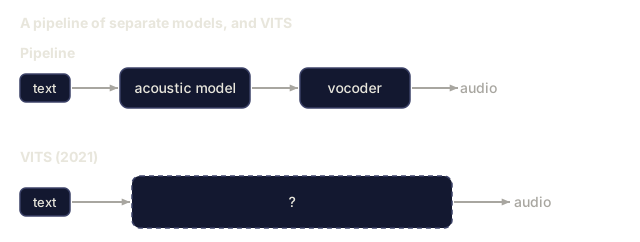
The modern TTS pipeline breaks into three stages:
- Text frontend. Normalize the text (dates, numbers, emails), convert it to phonemes or subword tokens, and predict prosody features.
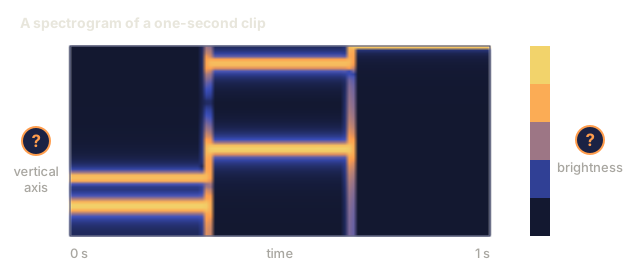
- Acoustic model. Text → mel spectrogram. Tacotron 2 (2017), FastSpeech 2 (2020), VITS (2021), F5-TTS (2024), Kokoro (2024).
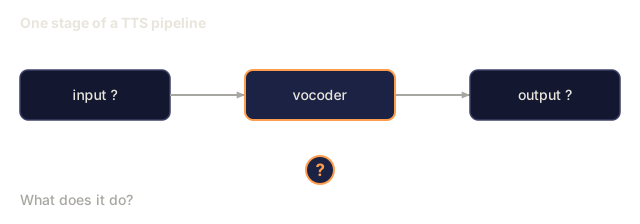
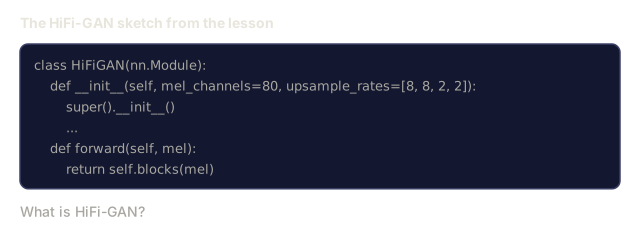
- Vocoder. Mel → waveform. WaveNet (2016), WaveRNN, HiFi-GAN (2020), BigVGAN (2022), neural codec vocoders from 2024 on.
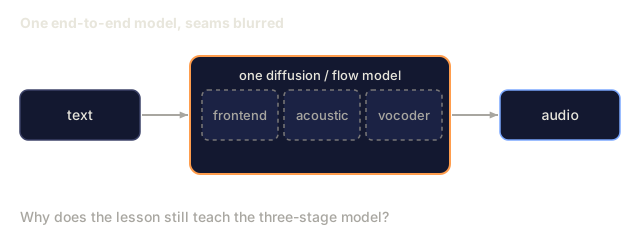
By 2026 the line between acoustic model and vocoder has blurred: end-to-end diffusion and flow-matching models (techniques that turn noise into structured output through iterative refinement, rather than one deterministic pass) collapse both stages into one. The three-part mental model still earns its keep when you're debugging, though: it tells you which stage produced the bad output.
The Concept

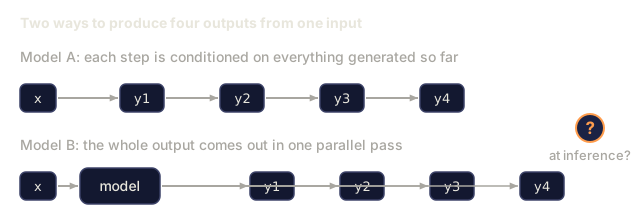
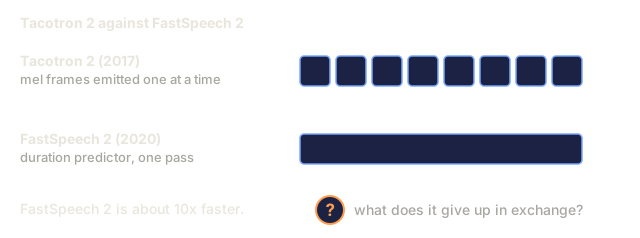
Tacotron 2 (2017). A seq2seq model: char-embedding → BiLSTM encoder → location-sensitive attention → autoregressive LSTM decoder, emitting mel frames one at a time. Slow, because it's autoregressive, and wobbly on long text, but still the baseline everyone cites.
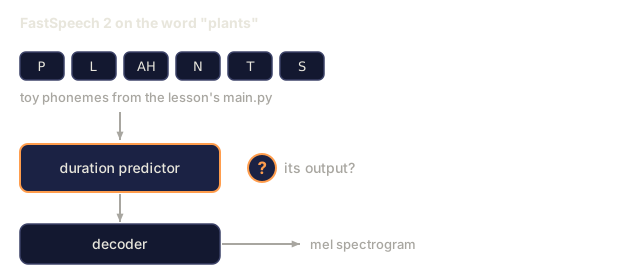
FastSpeech 2 (2020). Non-autoregressive: a duration predictor decides how many mel frames each phoneme gets, and the whole spectrogram comes out in one pass, 10× faster than Tacotron. It trades away some naturalness for that speed (monotonic alignment forces rigid timing), but it ships everywhere.
VITS (2021). Jointly trains an encoder, a flow-based duration model, and a HiFi-GAN vocoder end-to-end with variational inference: one model, high quality, and the dominant open-source TTS choice from 2022 to 2024. Variants include YourTTS (multi-speaker, zero-shot) and XTTS v2 (2024, Coqui).
F5-TTS (2024). A diffusion transformer over flow matching, with natural prosody and zero-shot voice cloning from 5 seconds of reference audio. Tops the 2026 open-source TTS leaderboards at 335M params.
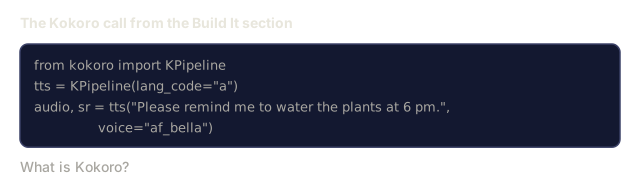
Kokoro (2024). Small at 82M params, runs on CPU, and is best-in-class English TTS for real-time use, though it's English-only with a closed vocabulary, licensed Apache 2.0.
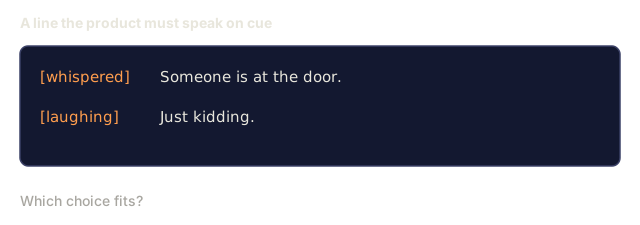
OpenAI TTS-1-HD, ElevenLabs v2.5, Google Chirp-3. Commercial state of the art. ElevenLabs v2.5's emotion tags ("[whispered]", "[laughing]") and character voices dominate audiobook production in 2026.
Vocoder evolution
| Era | Vocoder | Latency | Quality |
|---|---|---|---|
| 2016 | WaveNet | offline only | SOTA at release |
| 2018 | WaveRNN | ~realtime | good |
| 2020 | HiFi-GAN | 100× realtime | near-human |
| 2022 | BigVGAN | 50× realtime | generalizes across speakers/langs |
| 2024 | SNAC, DAC (neural codecs) | integrated with AR models | discrete tokens, bit-efficient |
By 2026 most "TTS" models run end-to-end from text to waveform. The mel spectrogram is just an internal representation now.
Evaluation
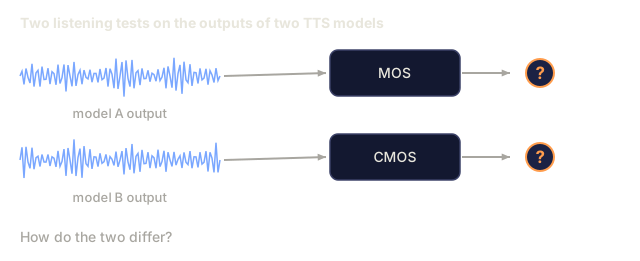
- MOS (Mean Opinion Score). 1–5 scale, crowd-sourced. Still the gold standard, and still painfully slow to collect.
- CMOS (Comparative MOS). A-vs-B preference judgment, with tighter confidence intervals per annotation than MOS.
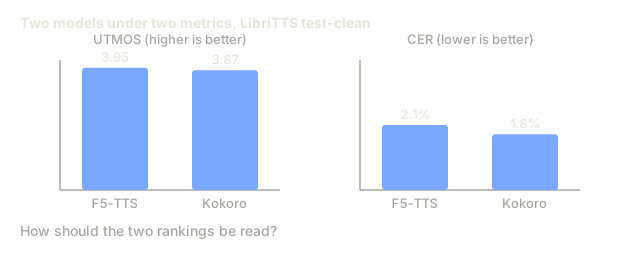
- UTMOS, DNSMOS. Reference-free neural MOS predictors; what the leaderboards actually run.
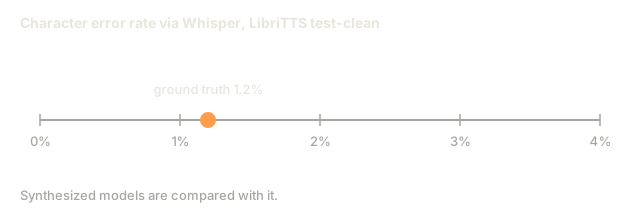
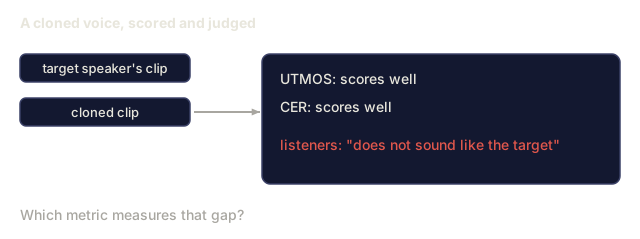
- CER (Character Error Rate) via ASR. Run the TTS output back through Whisper and compute CER against the input text: a cheap proxy for intelligibility.
- SECS (Speaker Embedding Cosine Similarity). Voice-cloning quality, measured directly.
2026 numbers on LibriTTS test-clean:
| Model | UTMOS | CER (via Whisper) | Size |
|---|---|---|---|
| Ground truth | 4.08 | 1.2% | — |
| F5-TTS | 3.95 | 2.1% | 335M |
| XTTS v2 | 3.81 | 3.5% | 470M |
| VITS | 3.62 | 3.1% | 25M |
| Kokoro v0.19 | 3.87 | 1.8% | 82M |
| Parler-TTS Large | 3.76 | 2.8% | 2.3B |
Build It
Step 1: phonemize input
Phonemes are the universal bridge between text and audio. Feed raw text to anything below VITS-level quality and pronunciation gets rough fast.
from phonemizer import phonemize
ph = phonemize("Hello world", language="en-us", backend="espeak")
# 'həloʊ wɜːld'
Step 2: run Kokoro (2026 CPU default)
Runs entirely offline, ships as a single file, and weighs in at 82M params.
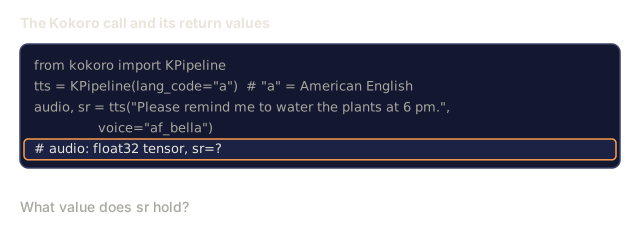
from kokoro import KPipeline
tts = KPipeline(lang_code="a")  # "a" = American English
audio, sr = tts("Please remind me to water the plants at 6 pm.", voice="af_bella")
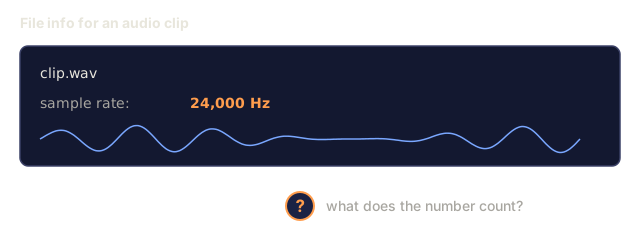
# audio: float32 tensor, sr=24000
Step 3: run F5-TTS with voice cloning
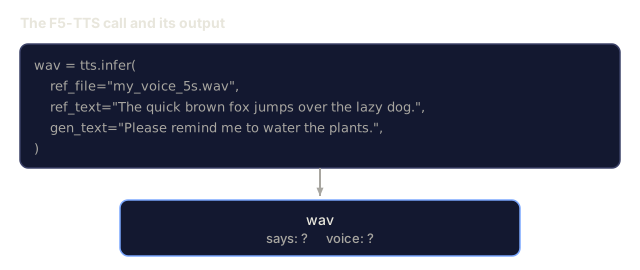
Pass a 5-second reference clip and its transcript, and F5 clones both the prosody and the timbre.
from f5_tts.api import F5TTS
tts = F5TTS()
wav = tts.infer(
    ref_file="my_voice_5s.wav",
    ref_text="The quick brown fox jumps over the lazy dog.",
    gen_text="Please remind me to water the plants.",
)
Step 4: HiFi-GAN vocoder from scratch
Too big to fit in a tutorial script, but the shape is:
class HiFiGAN(nn.Module):
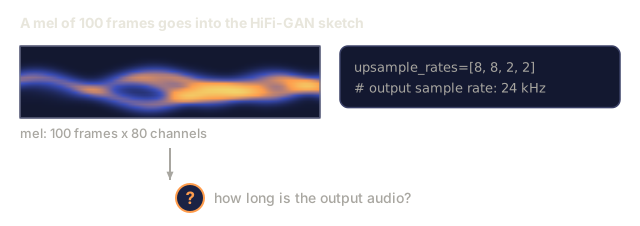
    def __init__(self, mel_channels=80, upsample_rates=[8, 8, 2, 2]):
        super().__init__()
        # 4 upsample blocks, total 256x to go from mel-rate to audio-rate
        ...
    def forward(self, mel):
        return self.blocks(mel)  # -> waveform
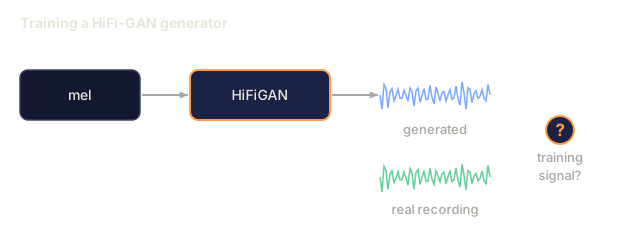
Training combines an adversarial loss (a discriminator judging short windows), a mel-spectrogram reconstruction loss, and a feature-matching loss. It's commoditized at this point: grab pretrained checkpoints from the hifi-gan repo or nvidia-NeMo instead of training from scratch.
Step 5: the full pipeline (pseudocode)
text = "Please remind me at 6 pm."
phones = phonemize(text)
mel = acoustic_model(phones, speaker=alice)      # [T, 80]
wav = vocoder(mel)                                # [T * 256]
soundfile.write("out.wav", wav, 24000)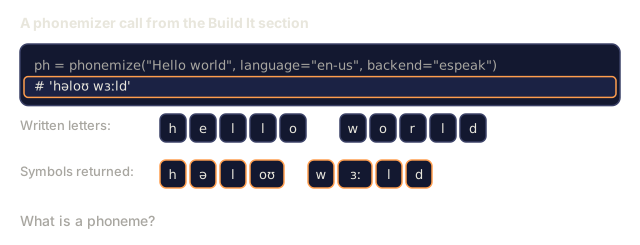
Use It
Picking a model in 2026 comes down to the situation:
| Situation | Pick |
|---|---|
| Real-time English voice assistant | Kokoro (CPU) or XTTS v2 (GPU) |
| Voice cloning from 5 s reference | F5-TTS |
| Commercial character voices | ElevenLabs v2.5 |
| Audiobook narration | ElevenLabs v2.5 or XTTS v2 + fine-tune |
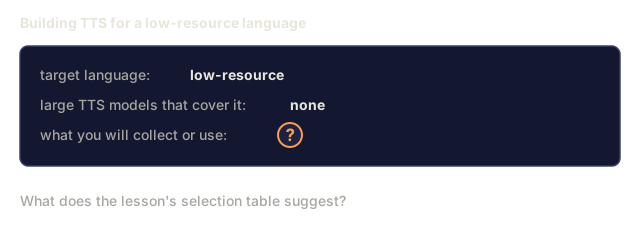
| Low-resource language | Train VITS on 5–20 h target-lang data |
| Expressive / emotion tags | ElevenLabs v2.5 or StyleTTS 2 fine-tune |
The open-source leaders as of 2026: F5-TTS for quality, Kokoro for efficiency. Don't reach for Tacotron unless you're a historian.
Pitfalls
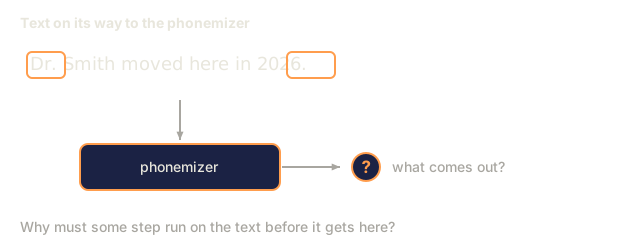
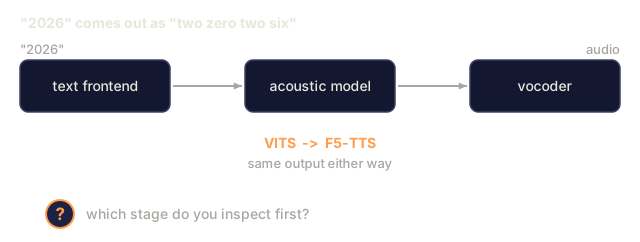
- No text normalizer. "Dr. Smith" reads as "Doctor" or "Drive"? "2026" as "twenty twenty six" or "two zero two six"? Normalize before the phonemizer ever sees the text.
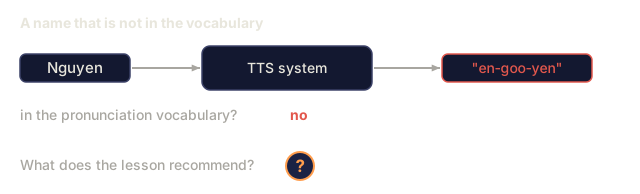
- OOV proper nouns. "Nguyen" → "en-goo-yen"? Ship a fallback grapheme-to-phoneme model for unknown tokens.
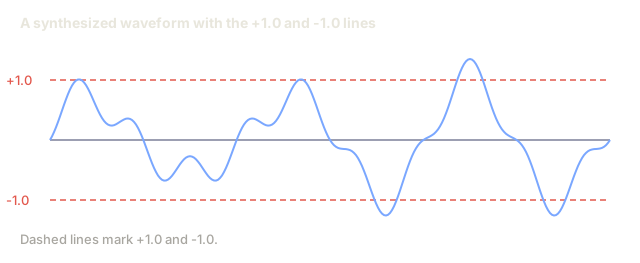
- Clipping. Vocoder output rarely clips on its own, but a mel-scaling mismatch at inference can overshoot ±1.0. Always call
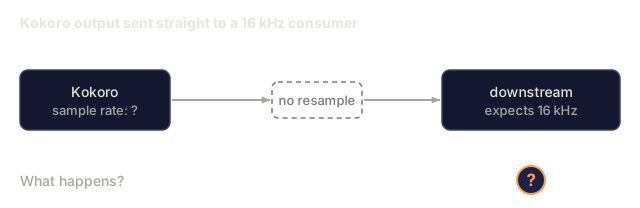
np.clip(wav, -1, 1). - Sample-rate mismatch. Kokoro outputs 24 kHz. If your downstream pipeline expects 16 kHz, resample it, or you'll get aliasing.
Ship It
outputs/skill-tts-designer.md is a reusable skill: pick a TTS model, voice, text-normalization scope, and evaluation plan for a given language, style, and latency target.
The three-stage mental model (frontend, acoustic model, vocoder) is worth keeping even once you're running an end-to-end diffusion model that hides those seams internally. Every real TTS bug I've chased down lived in the text frontend, not the neural network everyone wants to blame first. A model mispronouncing a date or a name is a normalization problem, not an acoustic one, and swapping VITS for F5-TTS won't fix a phonemizer that never saw the right input. Debug top-down: check what actually reached the acoustic model before you touch the model itself.
Exercises
- Easy. Run
code/main.py. It builds a phoneme dictionary from a toy vocab, estimates duration per phoneme, and prints a fake "mel" schedule. - Medium. Install Kokoro and synthesize the same sentence with voices
af_bellaandam_adam. Compare audio durations and subjective quality. - Hard. Record a 5-second reference clip of yourself, clone it with F5-TTS, and report the SECS between the reference and the cloned output.
Key Terms
| Term | What people say | What it actually means |
|---|---|---|
| Phoneme | Sound unit | Abstract sound class; 39 in English (ARPABet). |
| Duration predictor | How long each phoneme lasts | Non-AR model output; integer frames per phoneme. |
| Vocoder | Mel → waveform | Neural net mapping mel-spec to raw samples. |
| HiFi-GAN | Standard vocoder | GAN-based; dominant 2020–2024. |
| MOS | Subjective quality | 1–5 mean opinion score from human raters. |
| SECS | Voice-clone metric | Cosine similarity between target and output speaker embedding. |
| F5-TTS | 2024 open-source SOTA | Flow-matching diffusion; zero-shot cloning. |
| Kokoro | CPU English leader | 82M-param model, Apache 2.0. |
Further Reading
- Shen et al. (2017). Tacotron 2: the seq2seq baseline.
- Kim, Kong, Son (2021). VITS: end-to-end flow-based.
- Chen et al. (2024). F5-TTS: current open-source SOTA.
- Kong, Kim, Bae (2020). HiFi-GAN: the vocoder that still ships in 2026.
- Kokoro-82M on HuggingFace: 2024 CPU-friendly English TTS.
Code
- main.py (python, 135 lines)