Speech Recognition (ASR) — CTC, RNN-T, Attention
Speech recognition is audio classification at every timestep, glued together by a sequence model that knows English and silence. CTC, RNN-T, and attention are the three ways to do it. Pick one and understand why.
Learning Objectives
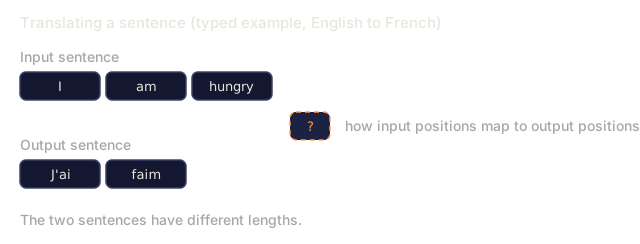
- Explain why ASR needs a dedicated alignment mechanism that plain classification doesn't: audio frames don't map one-to-one onto output characters, and output length isn't known in advance.
- Contrast CTC, RNN-T, and attention encoder-decoder on streaming ability, training cost, and offline quality, and name a real model that ships each one.
- Implement greedy CTC decoding and compute Word Error Rate (WER) from scratch, and state the WER thresholds for unusable versus human-parity transcription.
- Pick a 2026 ASR model, decoding strategy, and chunking scheme for a given deployment target: streaming, offline, edge, or domain-specific.
- Identify and avoid the pitfalls that still ship in production ASR: ungated silence hallucination, language-ID drift, and Whisper's 30-second window.
The Problem
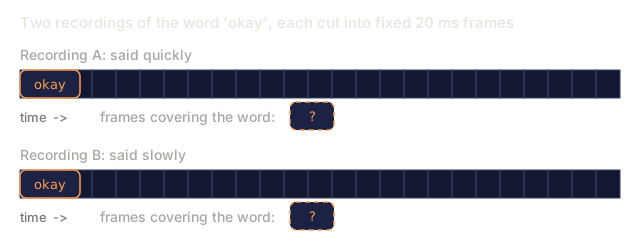
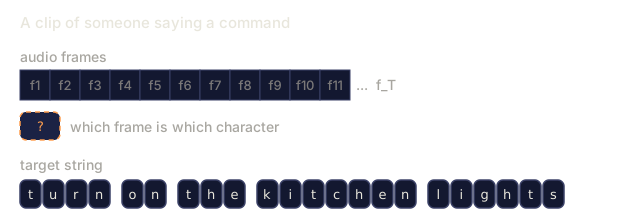
You have a 10-second, 16 kHz clip and you want a string out of it: "turn on the kitchen lights". The problem is structural, not perceptual. Audio frames don't line up one-to-one with characters: the word "okay" might take 200 ms or 1200 ms, silence punctuates the utterance, some phonemes just run longer than others, and you don't even know the output length in advance.
Three formulations solve this:
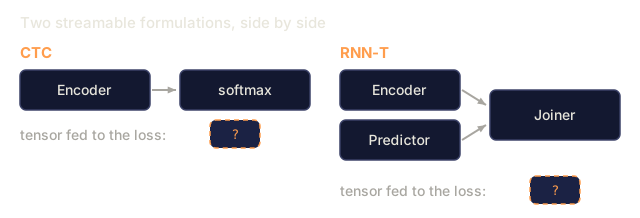
- CTC (Connectionist Temporal Classification). Emit per-frame token probabilities, including a special blank, then collapse repeats and blanks at decode time. Non-autoregressive and fast. Used by wav2vec 2.0, MMS.
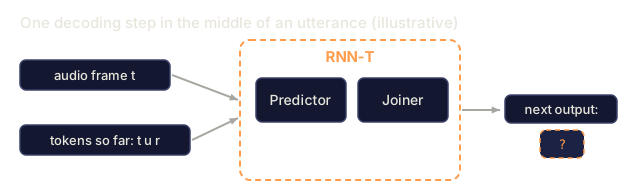
- RNN-T (Recurrent Neural Network Transducer). A joint network predicts the next token from the encoder frame and the token history. Streamable. Used by Google's on-device ASR, NVIDIA Parakeet.
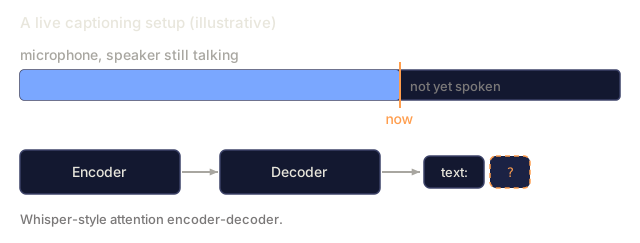
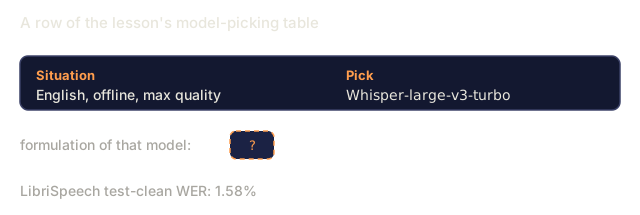
- Attention encoder-decoder. The encoder compresses audio into hidden states, and the decoder cross-attends to generate tokens autoregressively. Used by Whisper, SeamlessM4T.
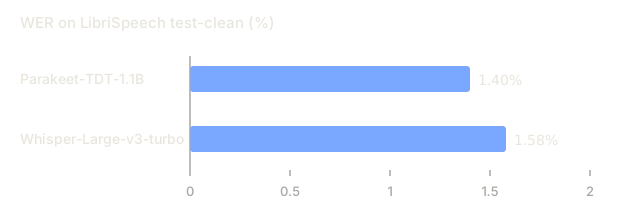
In 2026, SOTA WER on LibriSpeech test-clean sits at 1.4% (Parakeet-TDT-1.1B, NVIDIA) and 1.58% (Whisper-Large-v3-turbo). Barely any daylight between them on accuracy — the gap that actually matters is deployment.
The Concept

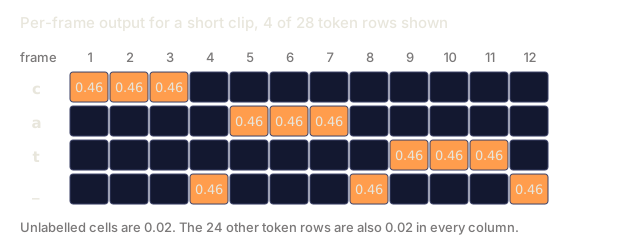
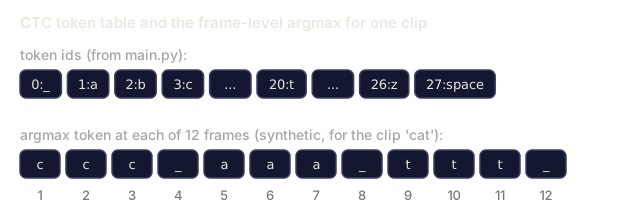
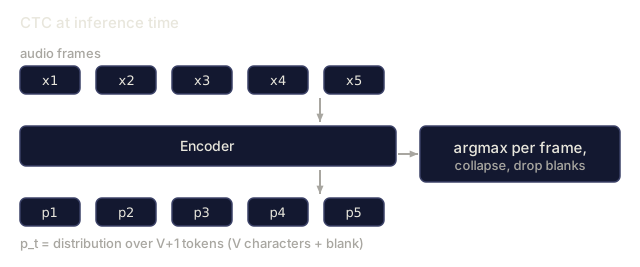
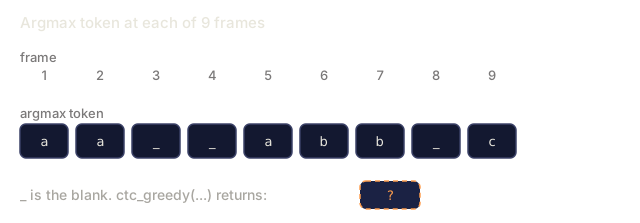
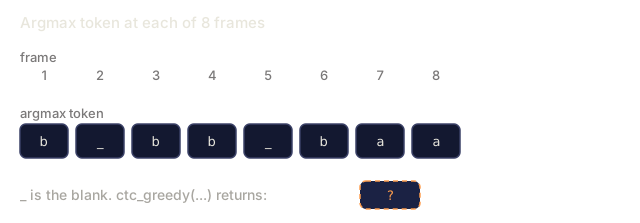
CTC intuition. Let the encoder output T frame-level distributions over V+1 tokens (V chars + blank). For a target string y of length U < T, any frame alignment that collapses to y counts, and CTC loss sums over all such alignments. Inference is simple: per-frame argmax, collapse repeats, remove blanks.
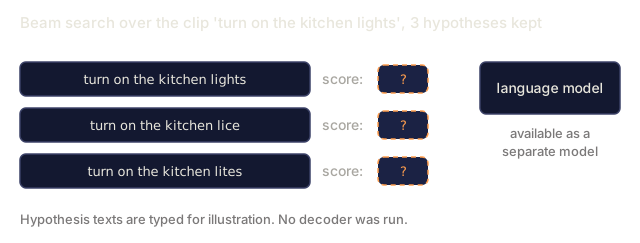
Advantages: non-autoregressive, streamable, zero lookahead. The drawback is the conditional independence assumption: each frame prediction is independent of the others, so there's no internal language model. You fix that with an external LM via beam search or shallow fusion.
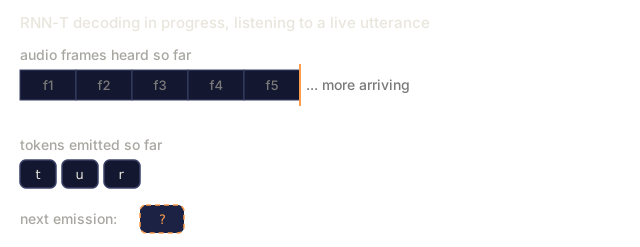
RNN-T intuition. RNN-T adds a predictor network that embeds the token history and a joiner that combines predictor state with the encoder frame into a joint distribution over V+1 (the +1 is a null / no-emit). That explicitly models the conditional dependence CTC ignores, and it's still streamable, because each step conditions only on past frames and past tokens.
Advantages: streamable, with an internal LM built in. Drawback: training is more complex and memory-hungry (a 3D loss lattice). RNN-T loss kernels are their own whole library category for that reason alone.
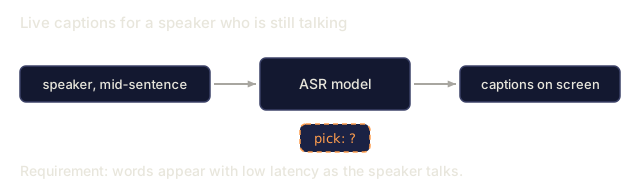
Attention encoder-decoder. An encoder (6-32 transformer layers) runs over log-mel frames, and a decoder (6-32 transformer layers) cross-attends to the encoder outputs to generate tokens autoregressively. There's no alignment constraint: attention can look anywhere in the audio. That's what makes it non-streamable unless you restrict attention (chunked Whisper-Streaming, 2024).
Advantages: the highest quality on offline ASR, and it's easy to train with standard seq2seq tooling. Drawback: autoregressive latency is proportional to output length, so it can't stream without extra engineering.
WER: the one number
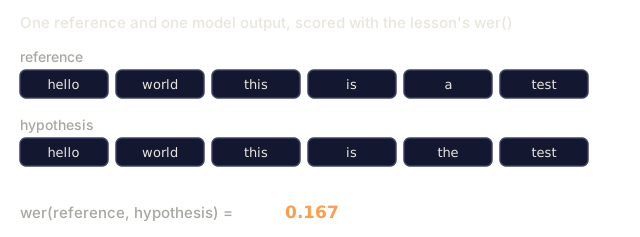
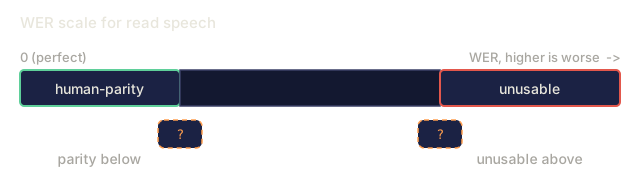
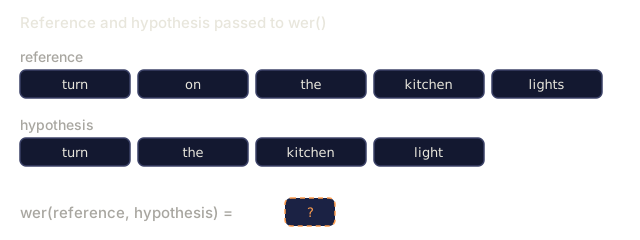
Word Error Rate = (S + D + I) / N, where S=substitutions, D=deletions, I=insertions, N=reference word count. It's the Levenshtein edit distance at the word level, and lower is better. A WER above 20% is generally unusable; below 5% counts as human-parity for read speech. 2026 numbers on standard benchmarks:
| Model | LibriSpeech test-clean | LibriSpeech test-other | Size |
|---|---|---|---|
| Parakeet-TDT-1.1B | 1.40% | 2.78% | 1.1B params |
| Whisper-Large-v3-turbo | 1.58% | 3.03% | 809M |
| Canary-1B Flash | 1.48% | 2.87% | 1B |
| Seamless M4T v2 | 1.7% | 3.5% | 2.3B |
All of these are encoder-decoder or RNN-T based. Pure CTC systems (wav2vec 2.0) sit around 1.8–2.1% on test-clean.
Build It
Step 1: greedy CTC decode
def ctc_greedy(frame_logits, blank=0, vocab=None):
    # frame_logits: list of per-frame probability vectors
    preds = [max(range(len(p)), key=lambda i: p[i]) for p in frame_logits]
    out = []
    prev = -1
    for p in preds:
        if p != prev and p != blank:
            out.append(p)
        prev = p
    return "".join(vocab[i] for i in out) if vocab else out
Two rules: collapse consecutive repeats, then drop blanks. Example: a a _ _ a b b _ c → a a b c.
Step 2: beam-search CTC
def ctc_beam(frame_logits, beam=8, blank=0):
    import math
    beams = [([], 0.0)]  # (tokens, log_prob)
    for p in frame_logits:
        log_p = [math.log(max(pi, 1e-10)) for pi in p]
        candidates = []
        for seq, lp in beams:
            for t, lpt in enumerate(log_p):
                new = seq[:] if t == blank else (seq + [t] if not seq or seq[-1] != t else seq)
                candidates.append((new, lp + lpt))
        candidates.sort(key=lambda x: -x[1])
        beams = candidates[:beam]
    return beams[0][0]
Production systems use prefix-tree beam search with LM fusion. What's above is the conceptual skeleton, not the real implementation.
Step 3: WER
def wer(ref, hyp):
    r, h = ref.split(), hyp.split()
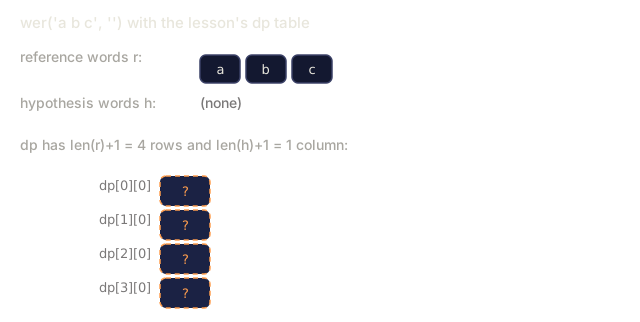
    dp = [[0] * (len(h) + 1) for _ in range(len(r) + 1)]
    for i in range(len(r) + 1):
        dp[i][0] = i
    for j in range(len(h) + 1):
        dp[0][j] = j
    for i in range(1, len(r) + 1):
        for j in range(1, len(h) + 1):
            cost = 0 if r[i - 1] == h[j - 1] else 1
            dp[i][j] = min(
                dp[i - 1][j] + 1,
                dp[i][j - 1] + 1,
                dp[i - 1][j - 1] + cost,
            )
    return dp[len(r)][len(h)] / max(1, len(r))
Step 4: inference against Whisper
import whisper
model = whisper.load_model("large-v3-turbo")
result = model.transcribe("clip.wav")
print(result["text"])
That's the strongest general ASR available in 2026, in one line — it runs on a 24 GB GPU at ~20× realtime.
Step 5: streaming with Parakeet or wav2vec 2.0
from transformers import pipeline
asr = pipeline("automatic-speech-recognition", model="nvidia/parakeet-tdt-1.1b")
for chunk in streaming_audio():
    print(asr(chunk, return_timestamps=True))
Streaming ASR needs chunked encoder attention and carryover state, so use a library that already handles it: NeMo for Parakeet, or the transformers pipeline with chunk_length_s.
Use It
The 2026 stack:
| Situation | Pick |
|---|---|
| English, offline, max quality | Whisper-large-v3-turbo |
| Multilingual, robust | SeamlessM4T v2 |
| Streaming, low latency | Parakeet-TDT-1.1B or Riva |
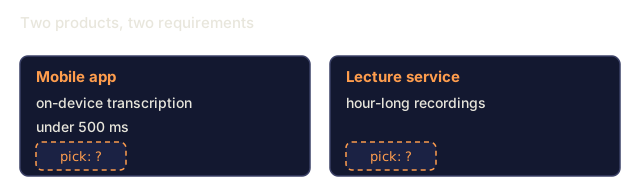
| Edge, mobile, <500 ms latency | Whisper-Tiny quantized or Moonshine (2024) |
| Long-form | Whisper with VAD-based chunking (WhisperX) |
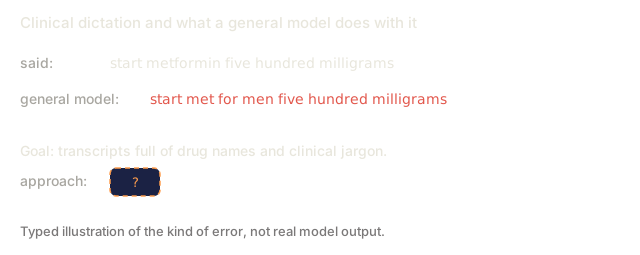
| Domain-specific (medical, legal) | Fine-tune wav2vec 2.0 + domain LM fusion |
Pitfalls that still ship in 2026
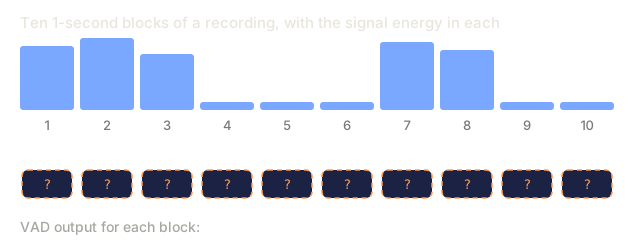
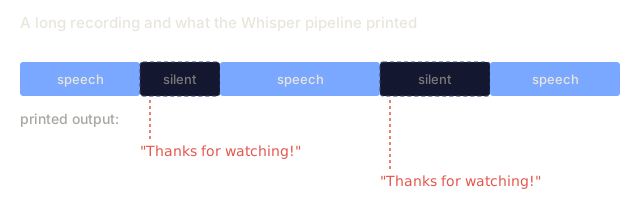
- No VAD. Running Whisper on silence produces hallucinations ("Thanks for watching!"). Gate it with VAD, always.
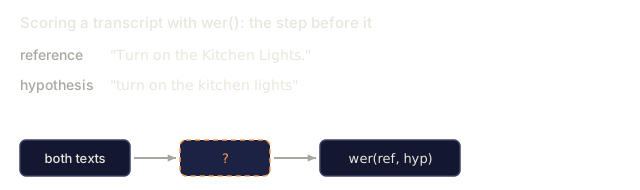
- Character vs word vs subword WER. Report word-level WER after normalization: lowercase, punctuation stripped.
- Language ID drift. Whisper's auto LID mis-routes noisy clips to Japanese or Welsh. Force
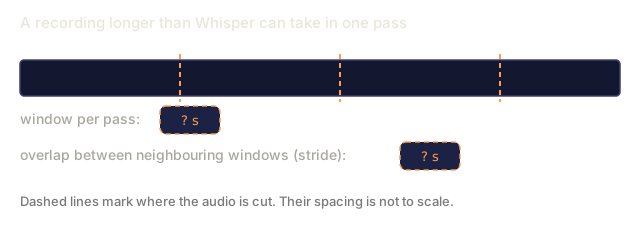
language="en"whenever you already know the language. - Long clips without chunking. Whisper has a 30-second window. Use
chunk_length_s=30, stride=5for anything longer.
Ship It
Save it as outputs/skill-asr-picker.md: pick model, decoding strategy, chunking, and LM fusion for whatever deployment target you're building for.
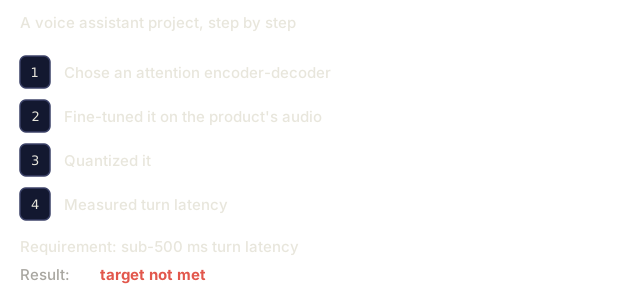
The mistake I see most often here is picking a formulation for the wrong reason. "Whisper is what everyone talks about, so we'll use Whisper" is not an engineering decision, and it falls apart the moment the product needs sub-500ms turn latency that an autoregressive decoder can't hit no matter how you quantize it. Work backward from your latency and streaming budget first. That alone usually narrows CTC, RNN-T, and attention down to one real option before WER ever enters the conversation. I've watched a team burn weeks fine-tuning an attention encoder-decoder for a voice assistant that needed RNN-T from day one, because nobody asked the deployment question before the accuracy question.
Exercises
- Easy. Run
code/main.py. It greedily decodes a hand-crafted CTC output and computes WER against a reference. - Medium. Implement the prefix-tree beam search in Step 2 properly (account for the blank merge rule). Compare with greedy on a 10-example synthetic dataset.
- Hard. Use
whisper-large-v3-turboon LibriSpeech test-clean. Compute WER on the first 100 utterances. Compare with published numbers.
Key Terms
| Term | What people say | What it actually means |
|---|---|---|
| CTC | The blank-token loss | Marginal over all frame-to-token alignments; non-AR. |
| RNN-T | The streaming loss | CTC + next-token predictor; handles word-order. |
| Attention enc-dec | Whisper-style | Encoder + cross-attending decoder; best offline quality. |
| WER | The number you report | (S+D+I)/N at word level. |
| Blank | The emptiness | Special token in CTC signalling "no emission this frame". |
| LM fusion | External language model | Add weighted LM log-probs during beam search. |
| VAD | The silence gate | Voice activity detector; trims non-speech. |
Further Reading
- Graves et al. (2006). Connectionist Temporal Classification: the CTC paper.
- Graves (2012). Sequence Transduction with RNNs: the RNN-T paper.
- Radford et al. / OpenAI (2022). Whisper: Robust Speech Recognition via Large-Scale Weak Supervision: the 2022 canonical paper, extended by v3-turbo in 2024.
- NVIDIA NeMo: Parakeet-TDT card: 2026 Open ASR Leaderboard leader.
- Hugging Face: Open ASR Leaderboard: live benchmark across 25+ models.
Code
- main.py (python, 156 lines)